What if we put the test at the beginning?
In Pavel’s description of N+1, the end goal sounds simple: find the next optimal task. Almost as simple as saying that an LLM’s job is to predict the next word. But deciding what to teach next contains a large part of the problem of how to teach.
Should the next task be easy or hard? Should we spend this moment on learning something new or keeping the student engaged? We want to improve their knowledge in six months, so all those decisions matter.
Here, I want to focus on one small piece of that system: the concept extractor.
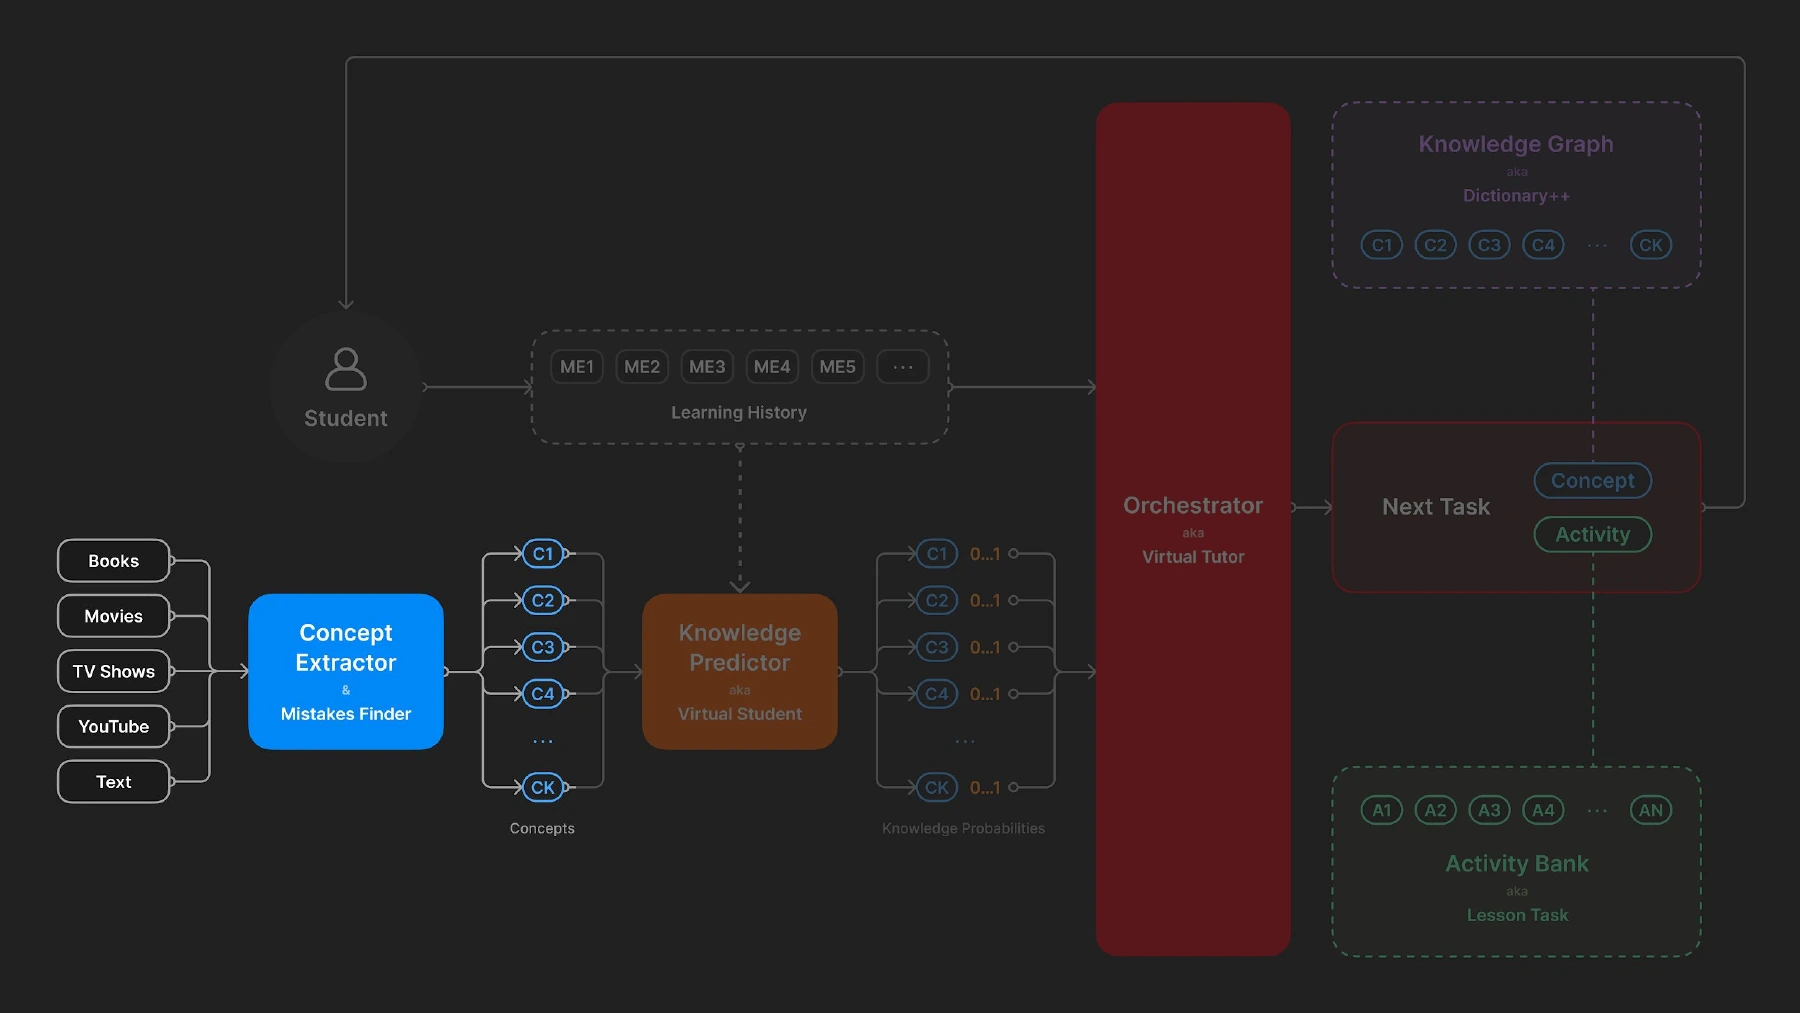
Imagine you have a book, a text, a movie — anything — and you already have your knowledge graph. How did you get it? That is a separate, big topic. For now, imagine it exists.
For English, it might include words and their different meanings, idioms, phrasal verbs, grammar rules and pronunciation rules. For mathematics, it might include the rules and skills used to solve a problem. The extractor’s job is to find which of those concepts appear in the material.
Can you be the concept extractor?
Let’s try it with English and mathematics. Your task is a little easier than the model’s: you do not have to search the entire knowledge graph. You get a few possible answers and choose one.
Sometimes you will identify a meaning or a skill. Sometimes you will see a student’s wrong solution and identify the misconception that led to the mistake. We will start with simple examples and gradually make them harder.
Later, we will get to how much money you could save us by doing this instead of a machine.
Choose an answer, then open the explanation. Enable JavaScript for scoring.
1. What does ‘bank’ mean here?
- The land beside a river
- A financial institution
- A reserve of something
- A row of similar objects
Show answer and explanation
A financial institution. Depositing savings points to a financial institution. The live quiz accidentally marked the riverbank answer as correct; this version fixes that key.Illustrative example · editorial explanation
A financial institution. Depositing savings points to a financial institution. The live quiz accidentally marked the riverbank answer as correct; this version fixes that key.Illustrative example · editorial explanation
2. Which mathematical skill is used in this step?
- Collecting like terms
- Factorising an expression
- Substituting values for variables
- Expanding brackets
Show answer and explanation
Expanding brackets. We multiply 3 by each term inside the brackets: 3 × x and 3 × 2. This expands the brackets using the distributive property.Illustrative example · editorial explanation
Expanding brackets. We multiply 3 by each term inside the brackets: 3 × x and 3 × 2. This expands the brackets using the distributive property.Illustrative example · editorial explanation
3. What does ‘took off’ mean here?
- Imitated someone for amusement
- Removed someone from their position
- Interrupted someone while speaking
- Helped someone leave a place
Show answer and explanation
Imitated someone for amusement. In this British English use, taking someone off means imitating them, usually humorously. The party and the laughter support that meaning.Illustrative example · editorial explanation
Imitated someone for amusement. In this British English use, taking someone off means imitating them, usually humorously. The party and the laughter support that meaning.Illustrative example · editorial explanation
4. Which concept explains the mistake in the student’s solution?
- Dividing by a variable can lose solutions
- A negative discriminant means no real roots
- Squaring can introduce extra solutions
- Two identical factors give a repeated root
Show answer and explanation
Squaring can introduce extra solutions. Squaring can introduce a solution that fails the original equation. Substituting −2 gives √4 = −2, or 2 = −2, which is false. Only x = 3 satisfies the original equation.Illustrative example · editorial explanation
Squaring can introduce extra solutions. Squaring can introduce a solution that fails the original equation. Substituting −2 gives √4 = −2, or 2 = −2, which is false. Only x = 3 satisfies the original equation.Illustrative example · editorial explanation
5. What does ‘rate’ mean here?
- A frequency relative to a unit of time
- A charge or payment per unit
- The speed of progress or change
- One quantity as a proportion of another
Show answer and explanation
One quantity as a proportion of another. “I rejected sense 1 because the attendance rate is not measured by time unit; it's measured as a proportion of votes attended (sense 4).”Written by a lexicographerAll three lexicographers agreed. “Sense 1” is the time-based option; “sense 4” is the proportion option.
One quantity as a proportion of another. “I rejected sense 1 because the attendance rate is not measured by time unit; it's measured as a proportion of votes attended (sense 4).”Written by a lexicographerAll three lexicographers agreed. “Sense 1” is the time-based option; “sense 4” is the proportion option.
6. What does ‘Now’ do in this sentence?
- At the present moment
- Used to preface a command or reproof or request
- (Prefatory or transitional) indicates a change of subject or activity
- In the immediate past
Show answer and explanation
(Prefatory or transitional) indicates a change of subject or activity. For this sentence, all three lexicographers selected “(prefatory or transitional) indicates a change of subject or activity”.lexEN · unanimous verdict from three lexicographersThe reviewers recorded their chosen sense but left no written explanation for this item.
(Prefatory or transitional) indicates a change of subject or activity. For this sentence, all three lexicographers selected “(prefatory or transitional) indicates a change of subject or activity”.lexEN · unanimous verdict from three lexicographersThe reviewers recorded their chosen sense but left no written explanation for this item.
7. Which meaning best fits ‘believes’?
- Accept as true; take to be true
- Be confident about something
- Follow a credo; have a faith; be a believer
- Judge or regard; look upon; judge
Show answer and explanation
Accept as true; take to be true. For this sentence, all three lexicographers selected “accept as true; take to be true”.lexEN · unanimous verdict from three lexicographersThe reviewers recorded their chosen sense but left no written explanation for this item.
Accept as true; take to be true. For this sentence, all three lexicographers selected “accept as true; take to be true”.lexEN · unanimous verdict from three lexicographersThe reviewers recorded their chosen sense but left no written explanation for this item.
The last three questions came from cases where the standard evaluation data had the wrong labels. Some definitions are very close, aren’t they? Keep that in mind. We will come back to those labels.
Imagine it works. What can we do with it?
Now you have a feel for concept extraction. The concepts can be items of knowledge, but they can also be skills. Did the student apply a particular skill in an essay? Which grammar rule did they use? Which rule did they misunderstand?
Imagine we have a magical extractor that does this perfectly. We give it text, audio or video, and it identifies the learning concepts. What could we use it for?
1. Find mistakes in student answers
We can look at a student’s answer, find a mistake and connect it to the concept they have not understood.
2. Prepare for a book or movie
We could help someone prepare for a book or a movie. Extract the concepts from the material. Combine them with the Knowledge Prediction model, a model that predicts what you already know, and we can identify what you need to learn beforehand.
This is especially useful for movies and audiobooks. When reading a book, stopping to look something up in a dictionary interrupts the flow. With a movie, it is worse: pause, open the dictionary, look up the word, continue. An awful experience if you want to enjoy the film.
3. Decide what to teach first
What about importance? Suppose you are preparing for an exam. Take the past papers from the last ten years, extract the concepts and count how often they appear. Now you have some evidence about what deserves more time.
There is a difficult question behind that: what should we teach? Pavel’s diagram is about how to teach, but our time is limited. Teaching one thing means we are not teaching something else. For example, if we can see which mathematical concepts students need in physics or chemistry, that helps us decide our priorities.
4. Find examples in familiar material
We can find an example of a concept in something you have already read or watched, or in material you like. We can connect a written explanation to a video showing the same thing. The concept extractor gives us a way to connect different resources.
5. Notice spontaneous practice
You are teaching a particular maths concept, but while solving the task, the student demonstrates that they know something else. We can notice that and remember it, helping us personalise their learning path more accurately.
6. Recognise knowledge across subjects
The same thing can happen across subjects. A student does a physics task and shows that they understand a mathematical rule. That is useful information for their learning path, even though we were not explicitly testing the rule.
7. Check generated exercises
If we ask an LLM to create an exercise for a particular concept, does the exercise actually test that concept? We can use the extractor to check.
How do we use this in Glite?
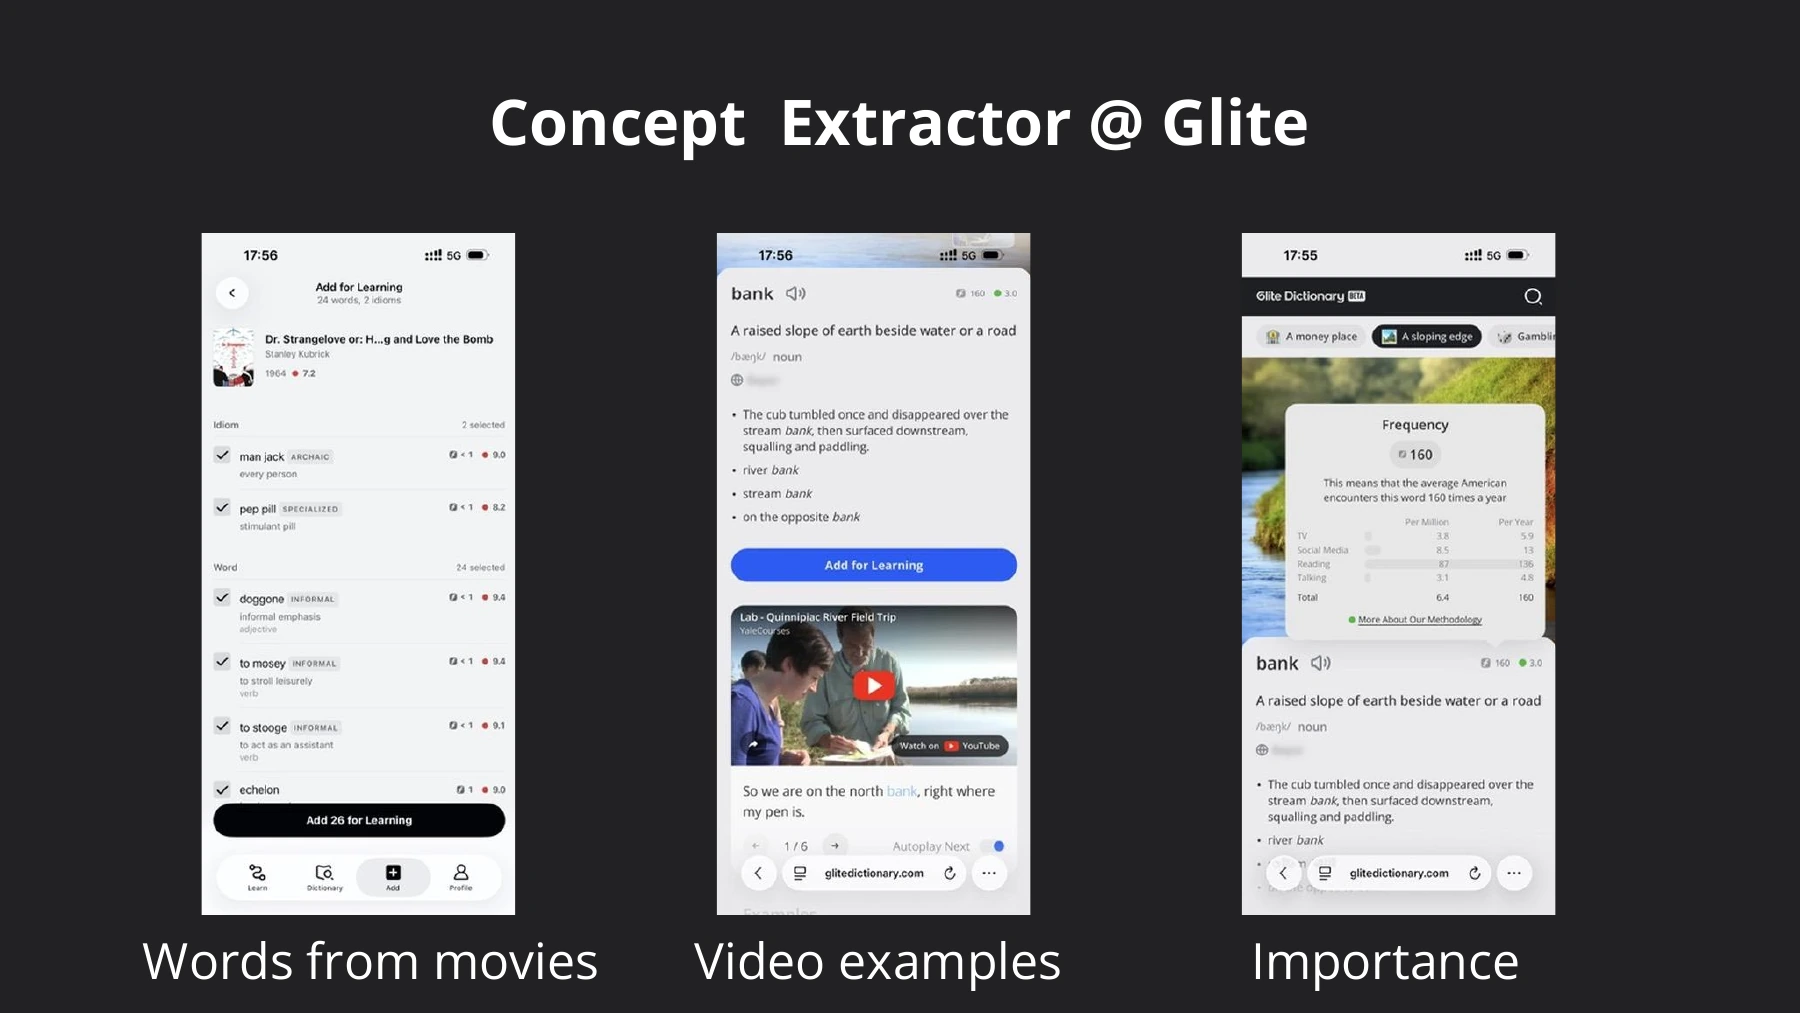
One use is learning the meanings, idioms and phrasal verbs from a movie before watching it. And the gaps are not always obvious.
I was watching Line of Duty recently, and they used the word grass. I thought I knew that word. Apparently, there was another meaning I did not know.
If we identify that meaning in advance and predict that you do not know it, you can learn it before the film. Then the film gives you much more to remember: the emotions, the characters, the situation, the pronunciation. You knew the meaning a little already; now you meet it in a scene.
A second use is finding video examples. When I am learning a word, idiom or phrasal verb, I want to see how real people use it. And I want examples of that particular meaning. If I am learning bank as the bank of a river, examples about depositing money are not what I need.
We also calculate importance. Not every meaning is equally useful to every learner. A meaning may be common in spoken language and rare in academic writing, or the other way around. Its importance depends on what you want to do.
Do we teach the different meanings of a word, and how they relate to one another? Yes. Our app is designed for learners who are past the beginner stage — often people who have already spent three to five years studying the language.
They already know the basic meanings of many words. The other meanings become especially important. We need to explain the differences and the connections. You cannot just learn words.
So how do we build the extractor that makes this possible? There are two fundamental architectures.
How do we find the right concept?
Take the sentence “She deposited cash at the bank.” We have a set of possible concepts, and we want to match bank in this sentence to “financial institution”.
In English, we can first remove definitions that do not belong to the word bank. Mathematics is harder. We might have ten thousand possible concepts, and there is no simple word filter that tells us which ones to consider.
The first architecture is a bi-encoder. One encoder turns the word in its context into an embedding — a vector, or list of numbers. Another encoder turns each concept’s definition into a vector.
We train them together so that the matching vectors have a high similarity score. The vector for bank in our sentence should match the vector for “financial institution”. Then we search for the closest concept.
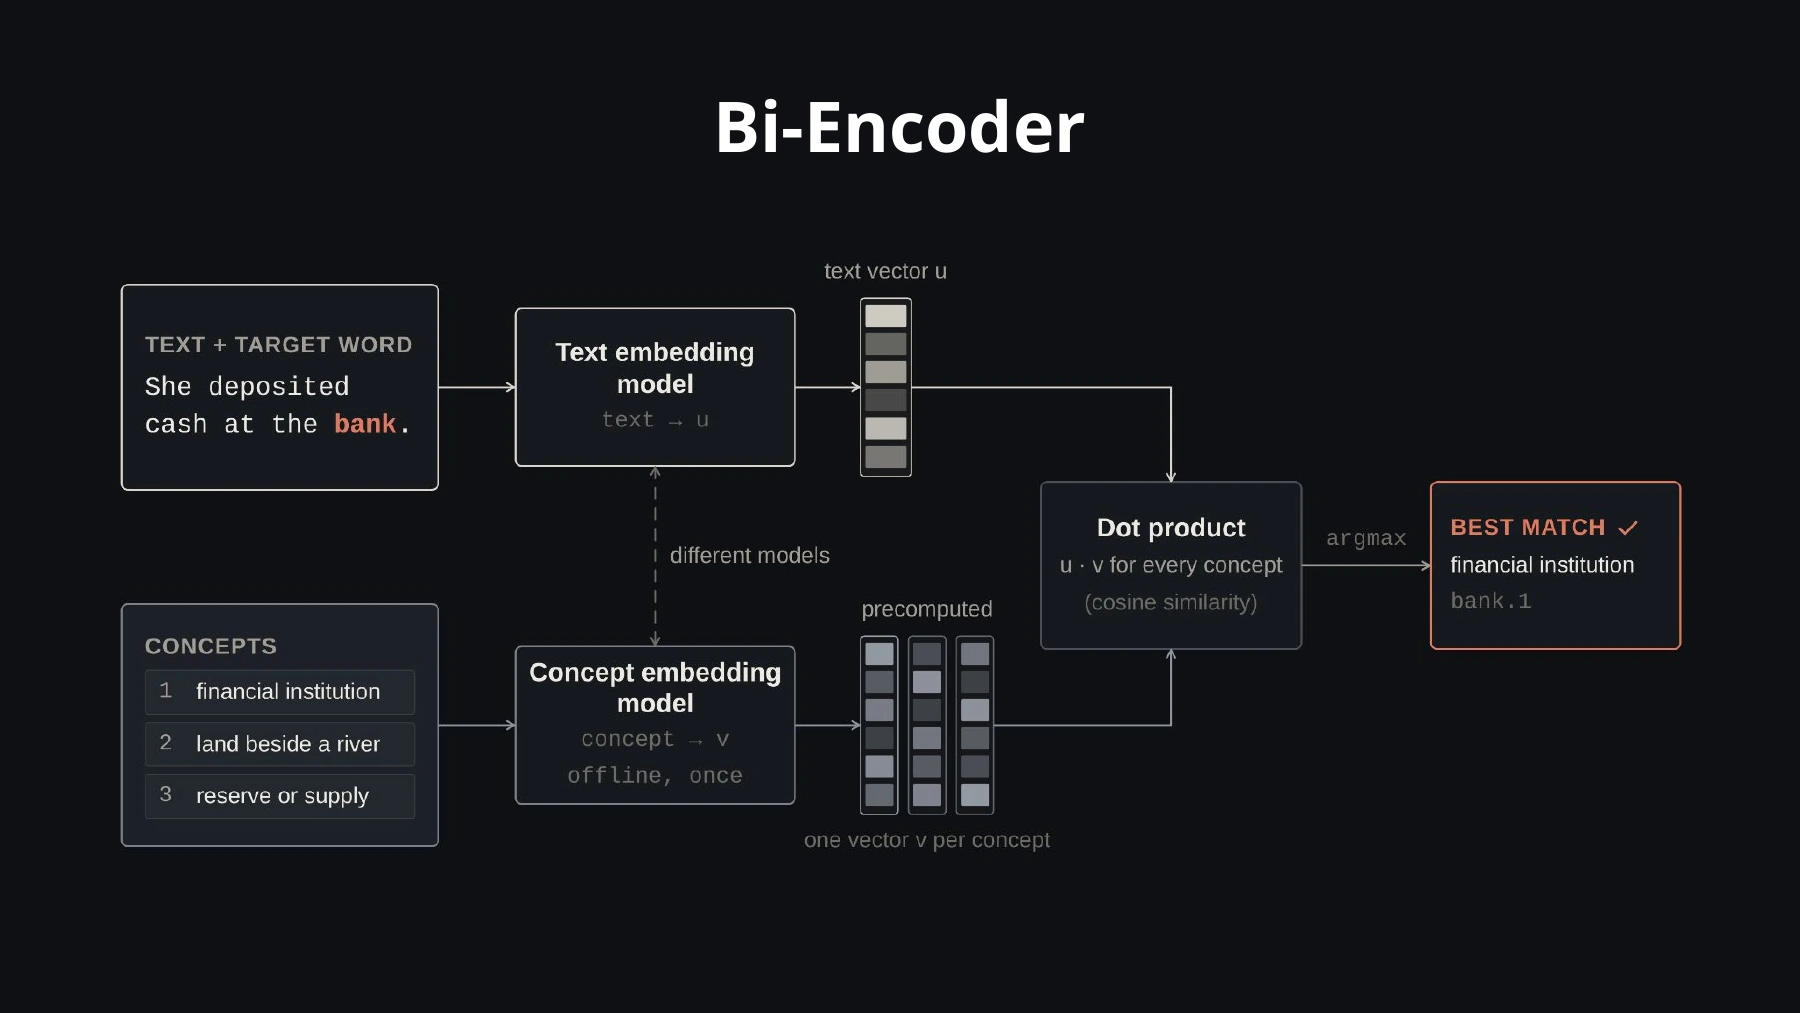
This is fast. We can calculate all the concept vectors in advance and store them. For each new piece of text, we calculate its vector and search the prepared collection.
Of course, we still need to train those encoders. Where does the training data come from? We will get to that.
The second architecture is a cross-encoder. It reads the context together with candidate definitions and scores how well they match.
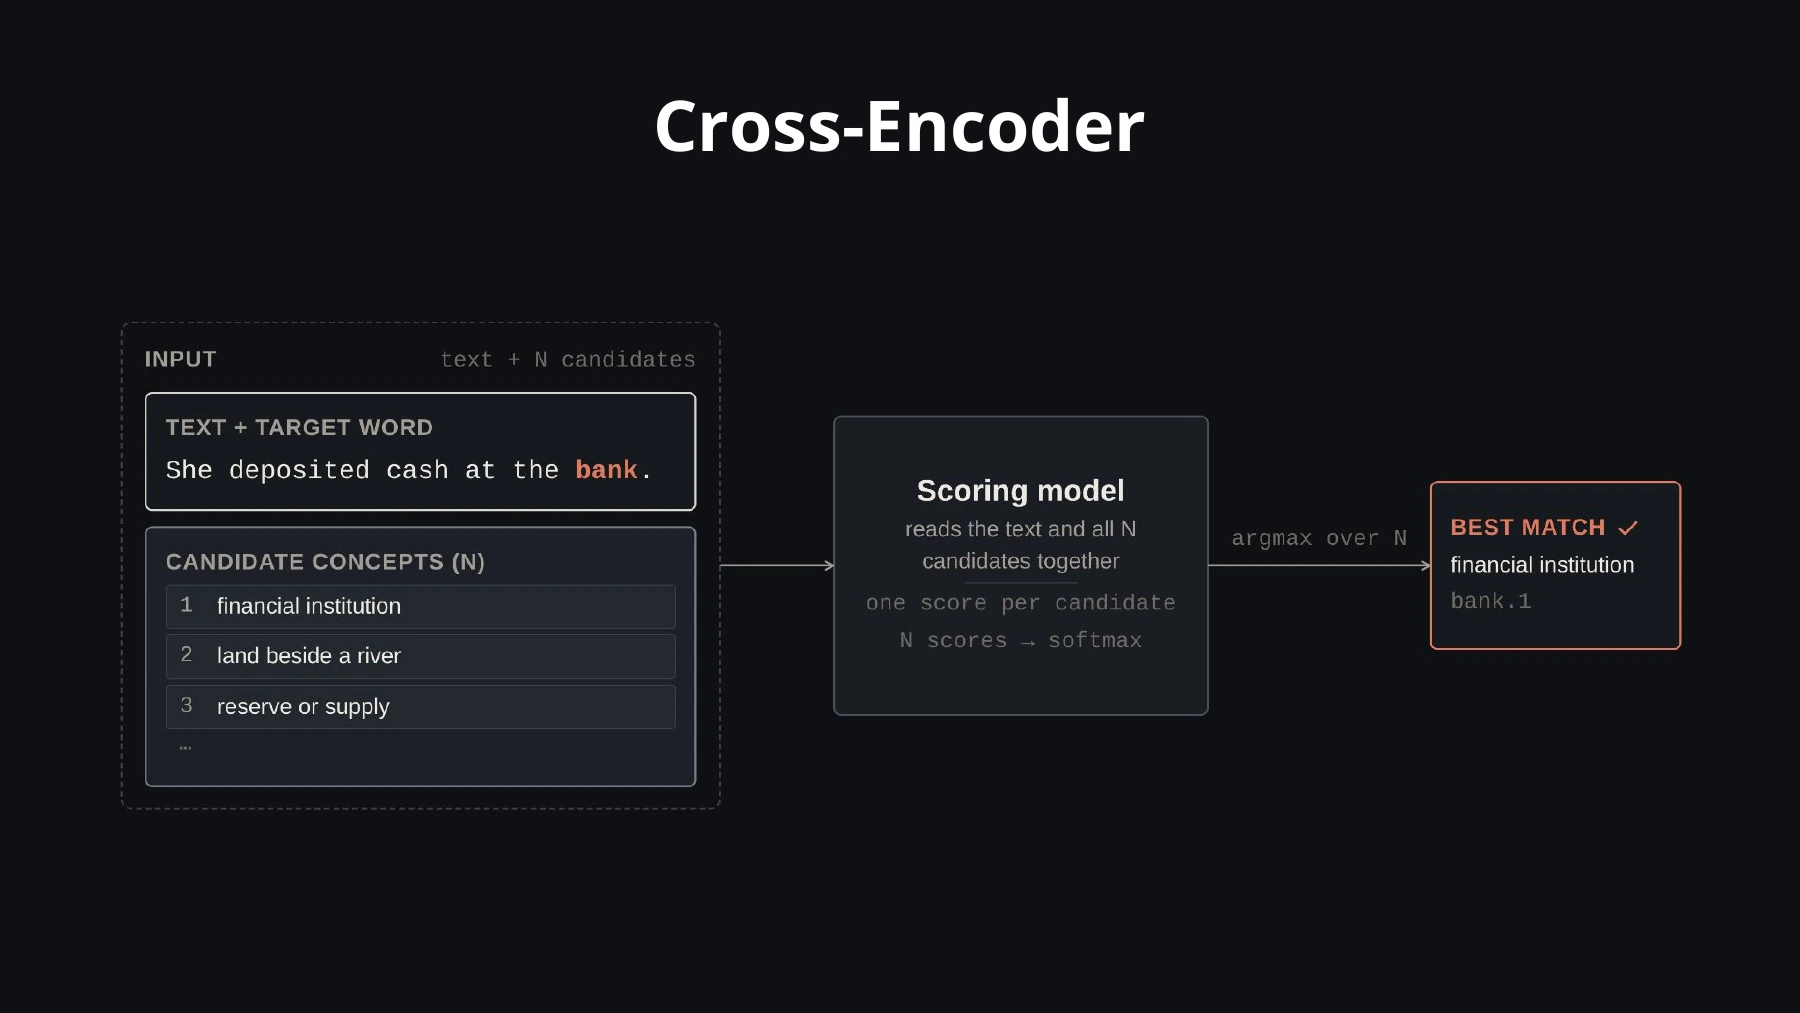
This usually gives a better comparison, but it is slower. We cannot do the same precomputation, because the model needs to read the context and the candidate together.
And what happens when we have ten thousand mathematical concepts? Comparing them all this way is a lot of work. We need to narrow the search.
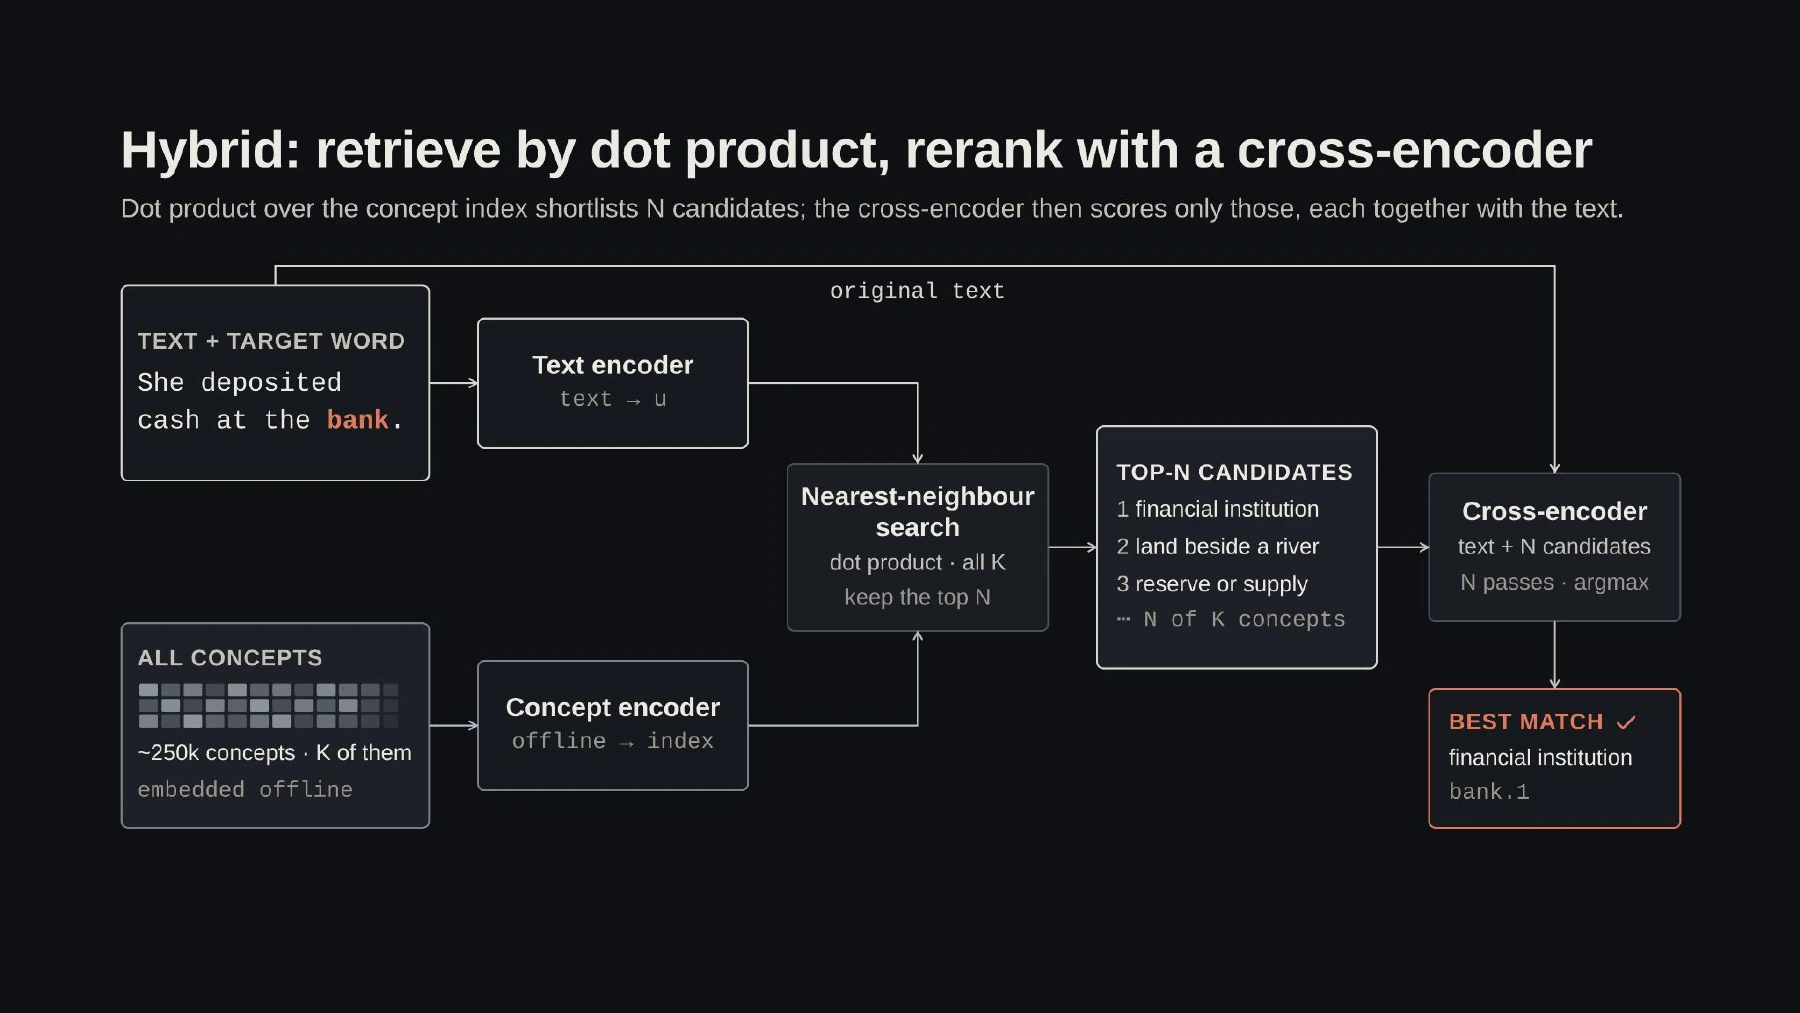
So we combine the two approaches. The bi-encoder selects the best ten or twenty candidates, and a cross-encoder chooses among them. That is the hybrid approach.
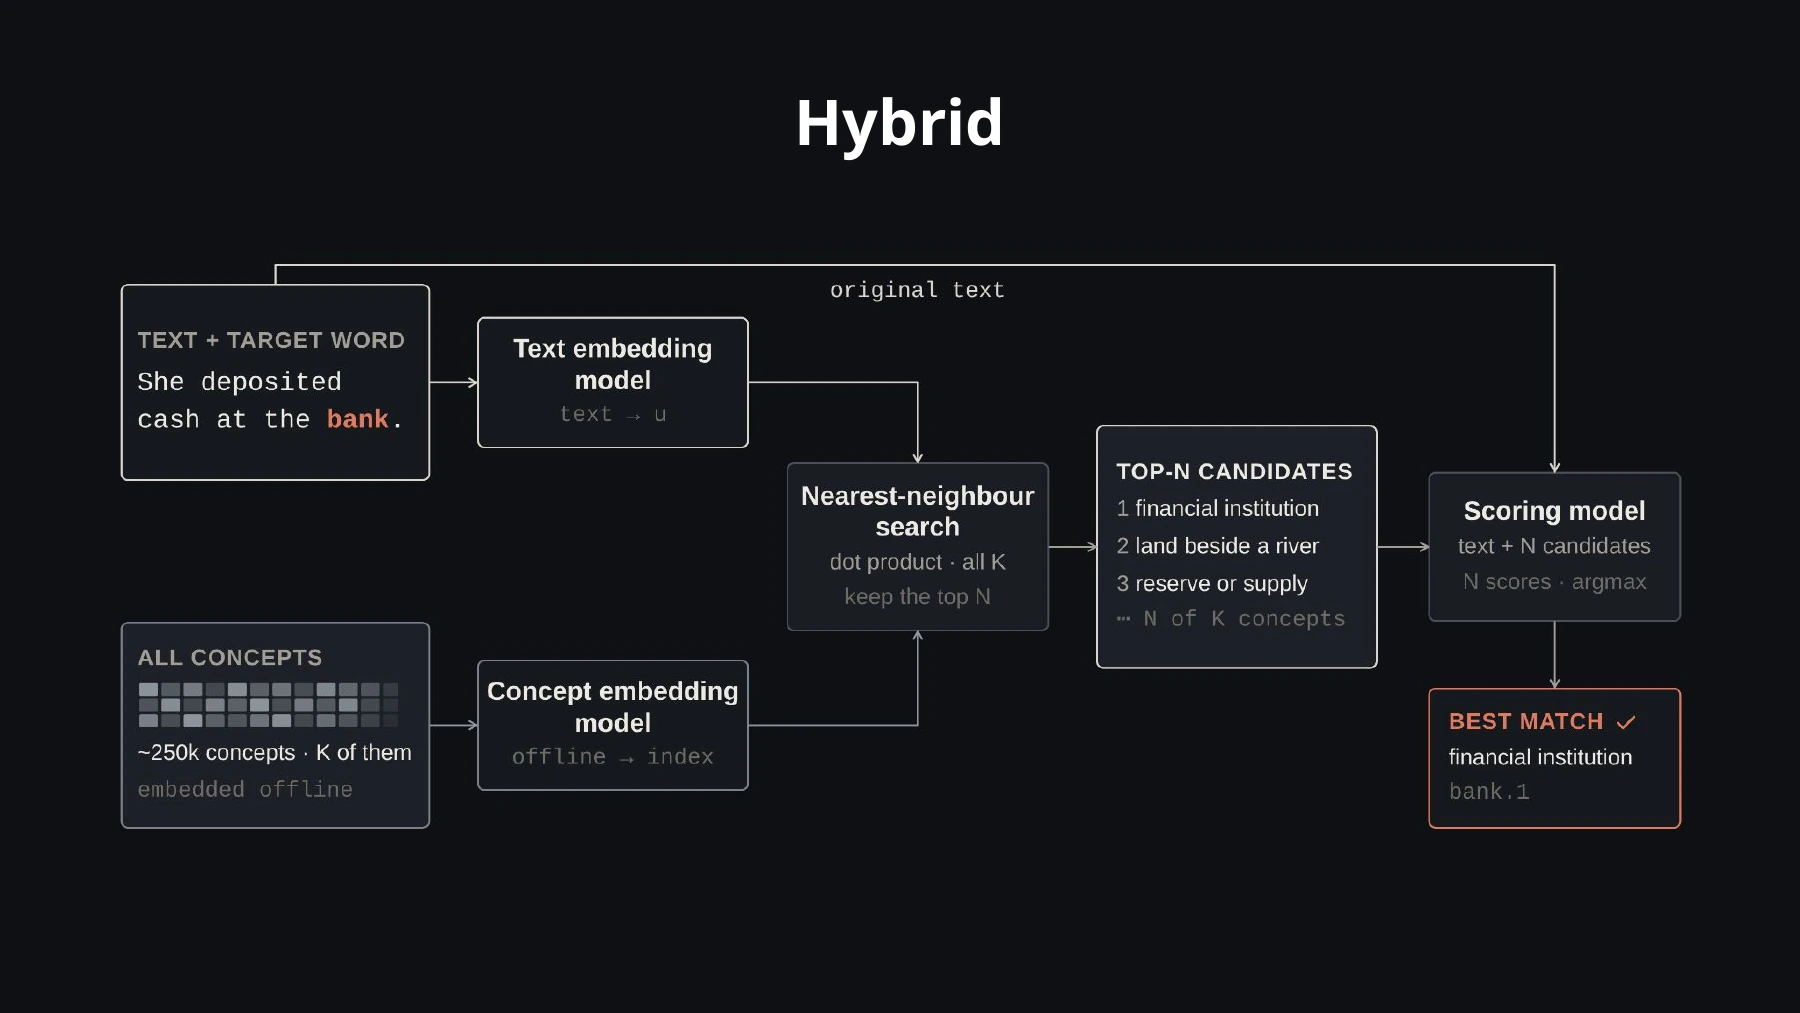
For many practical tasks, this is the way to go. Now we have the basic architectures. But there is an obvious question.
Where are the LLMs?
LLMs are everywhere. How well do they do this job?
Our paper, English Word Sense Disambiguation in 2026: When the Labels Become the Bottleneck, looks at this question for English word meanings. Word-sense disambiguation is the task you tried in the quiz: choosing the meaning used in a particular context.
First, let’s look at where the field of word-sense disambiguation stood in June 2026, before our paper. The picture below shows results on the widely used Raganato evaluation set. We have specialised models — bi-encoders, cross-encoders and more elaborate systems — alongside LLMs. The LLMs appear to be behind the best specialised system, SANDWiCH.
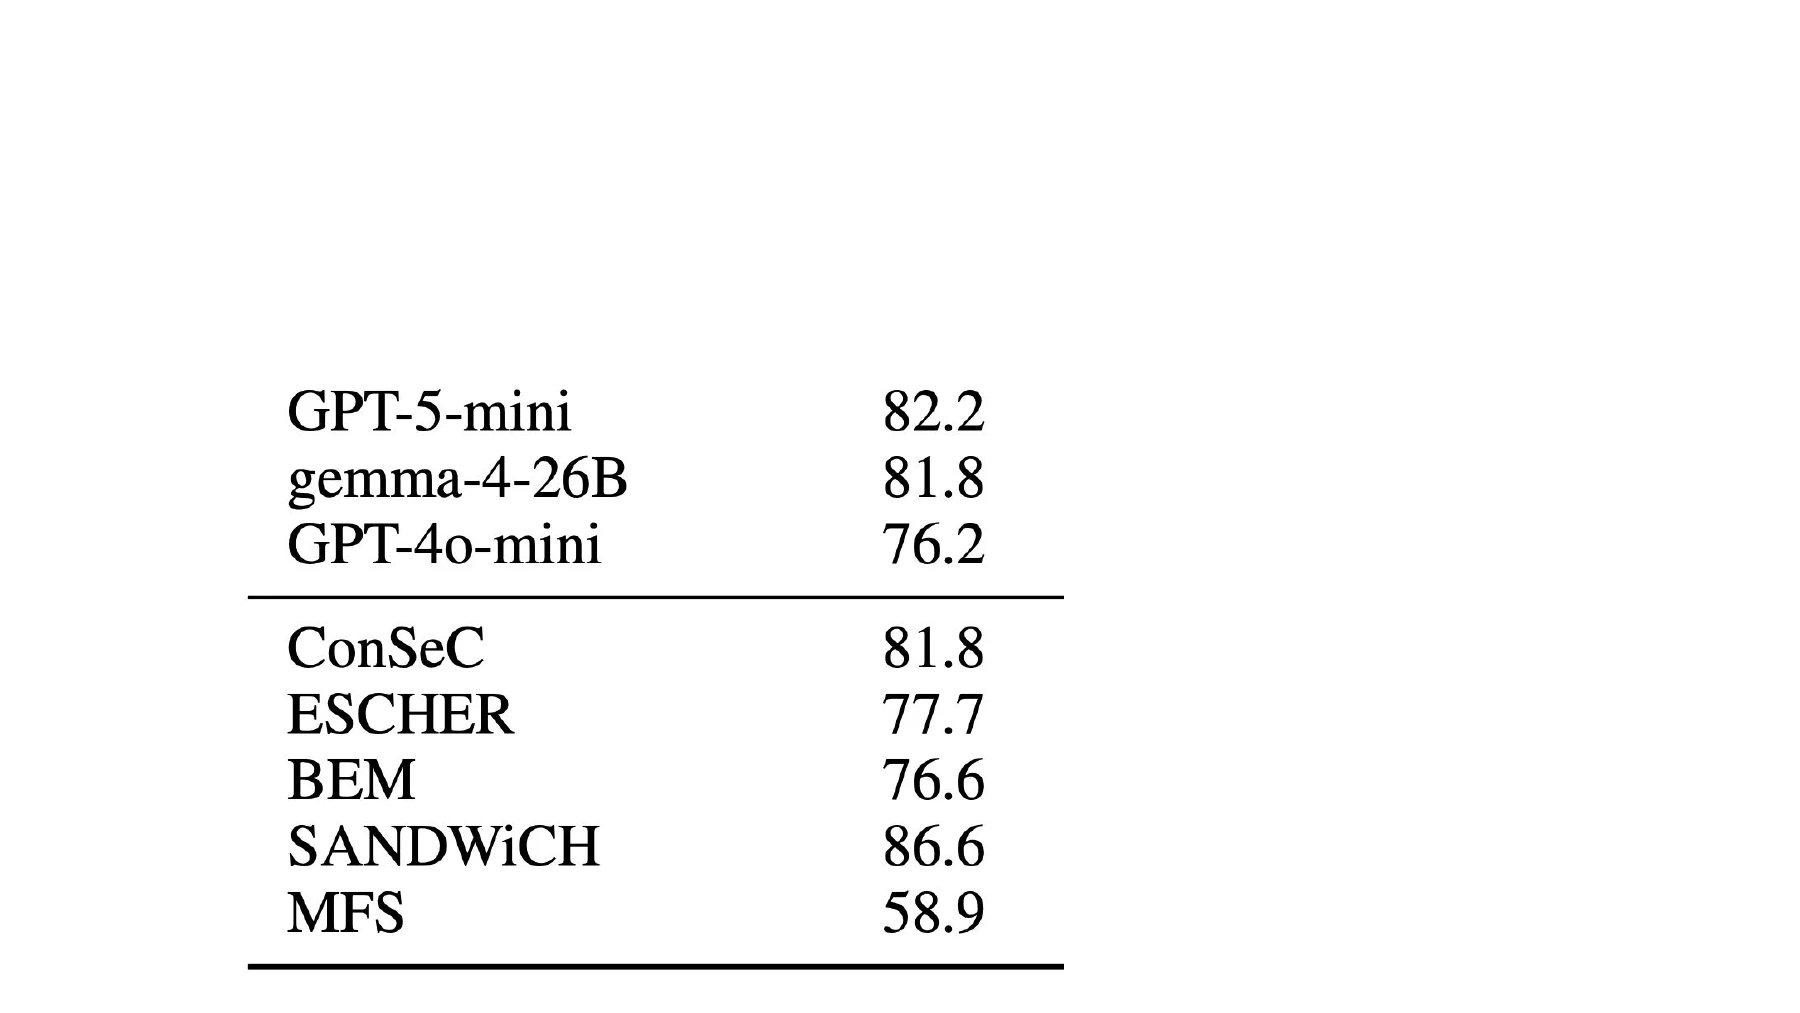
Now, let’s add stronger LLMs: GPT-5.5, Gemini 3.1 Pro and Claude Fable 5. Their scores are higher. They are still below SANDWiCH, but now they are close.
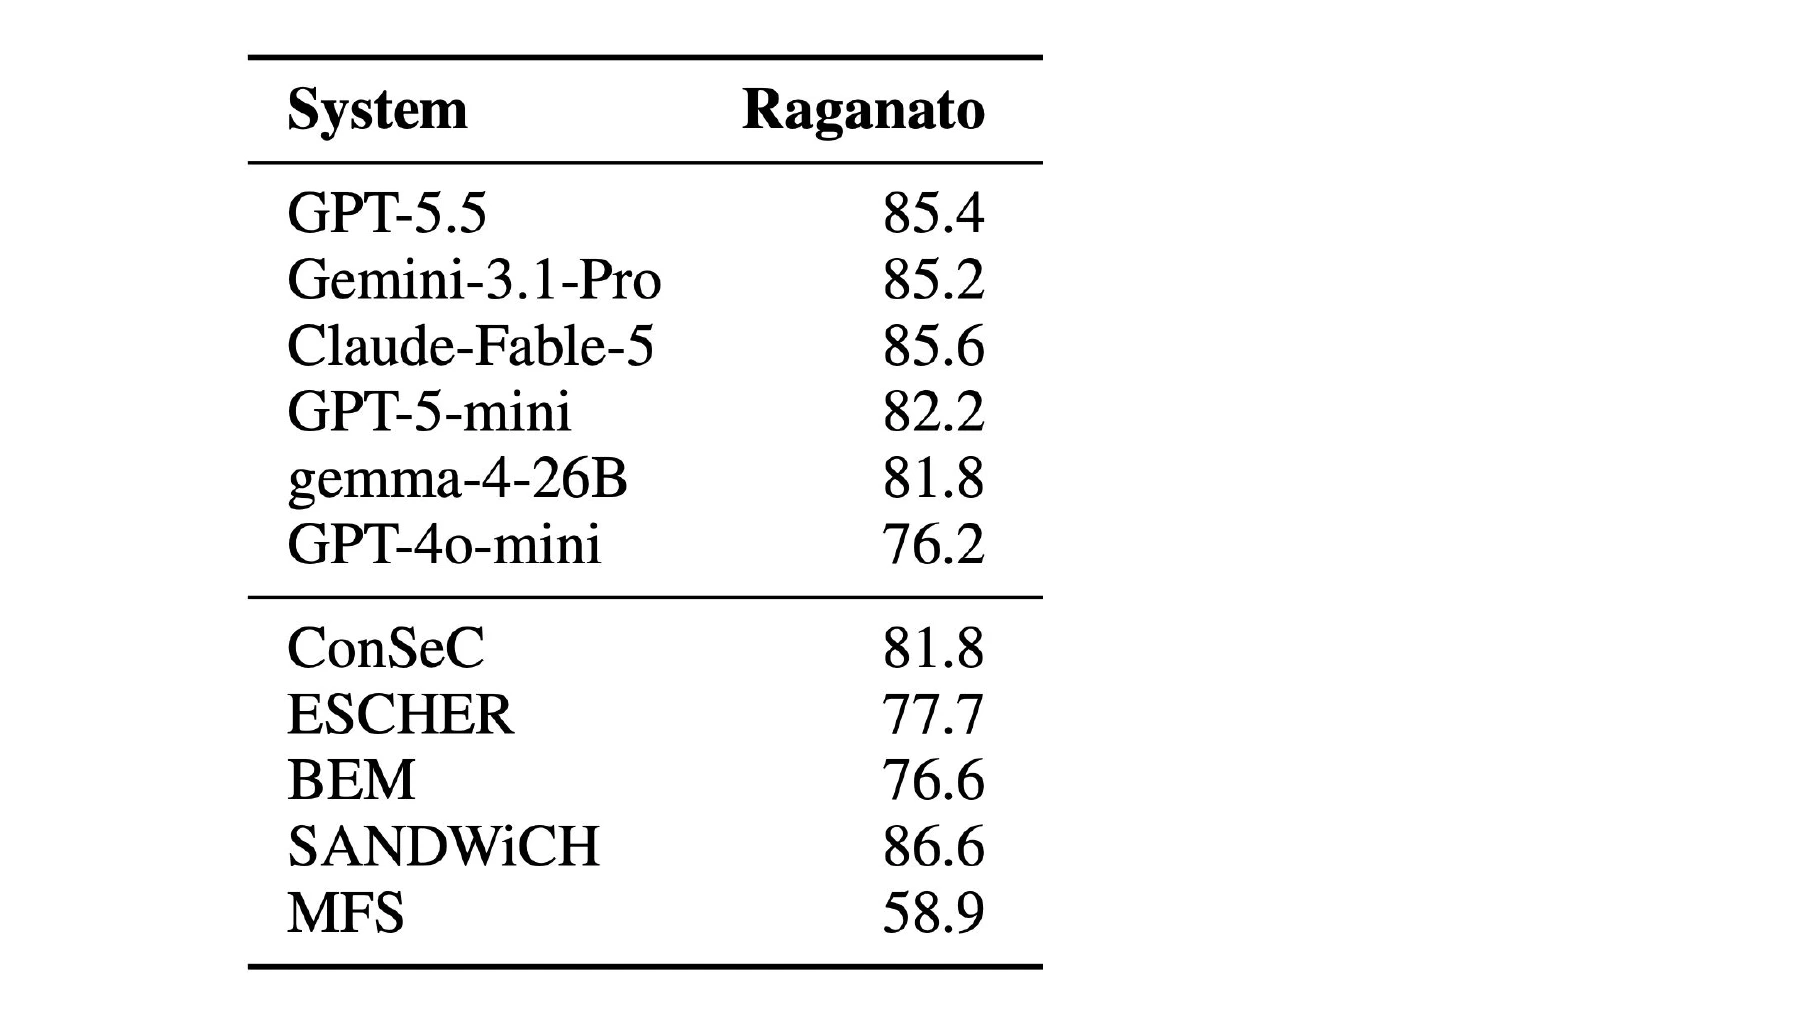
But this is the wrong picture. Remember the last three quiz questions? Those were examples of mistakes in the evaluation labels.
Maru and colleagues had already investigated this in 2022 and produced corrected labels. When we evaluate against those, most models score higher.
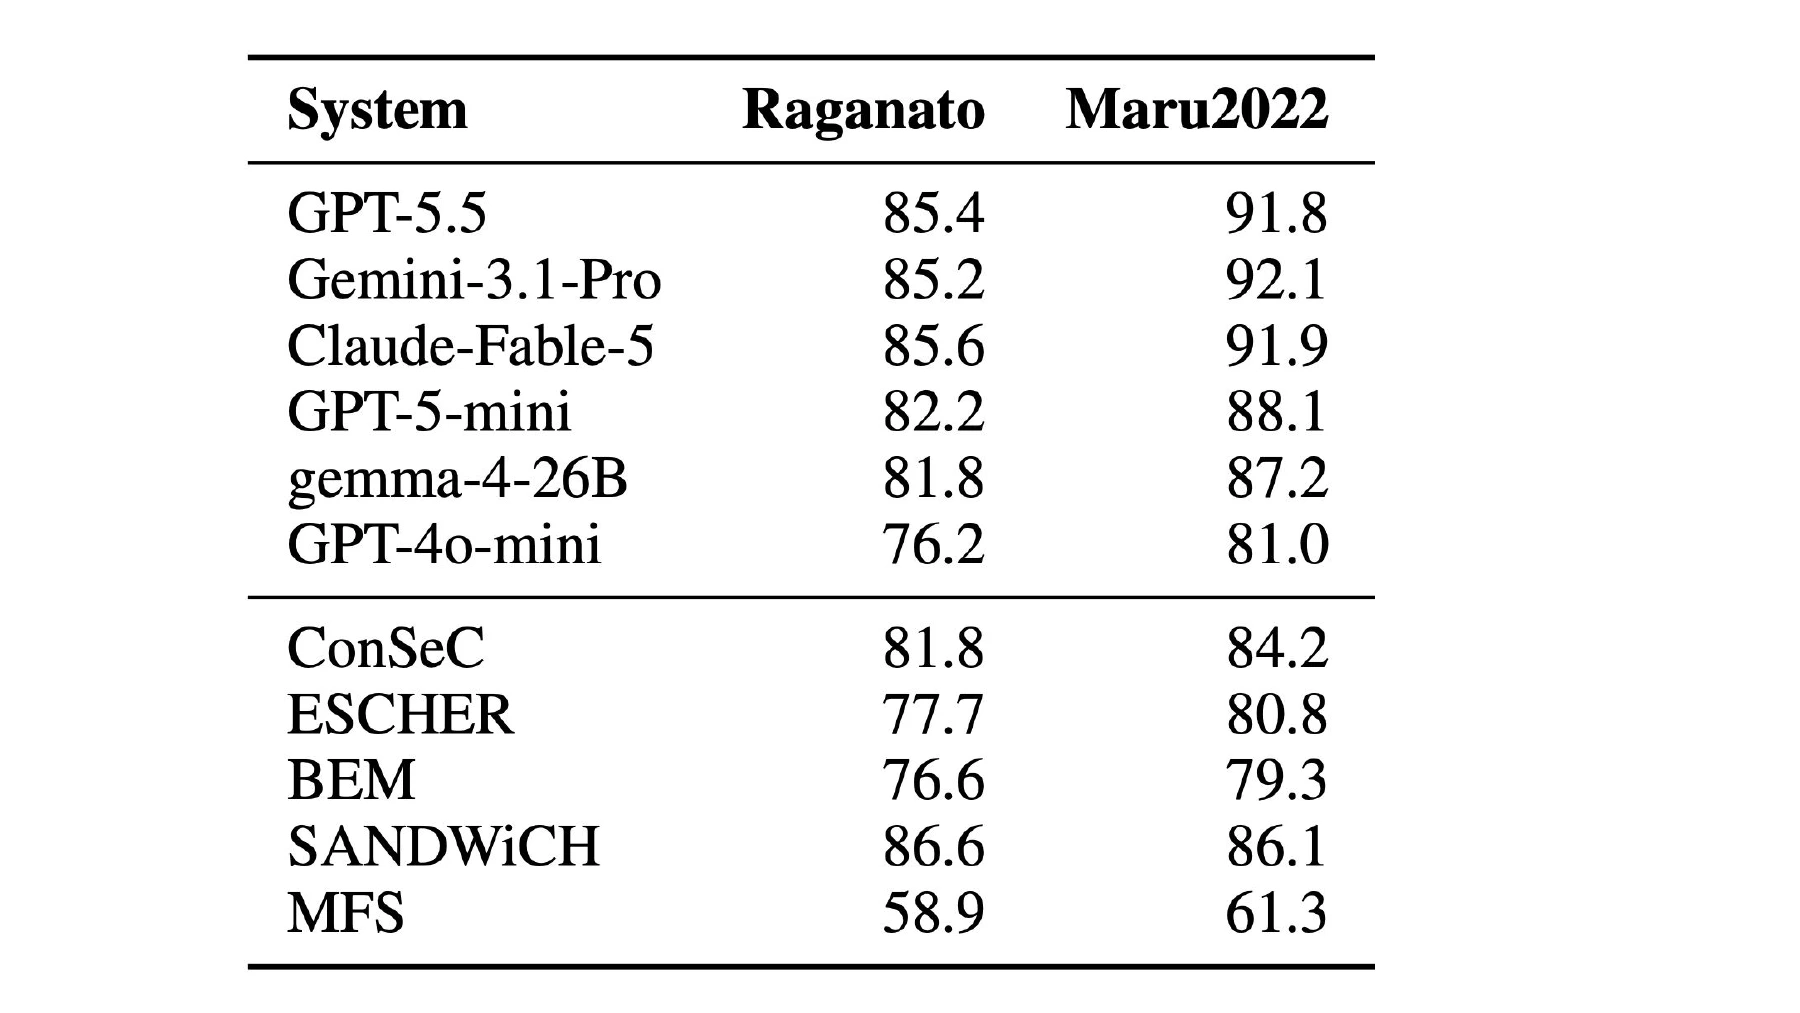
Even that version still had mistakes. We identified about 7% of the items as particularly suspicious and asked three professional lexicographers to review them independently. These are people who create dictionaries for a living.
We used their judgments to make further corrections in lexEN. Now look at the final column.
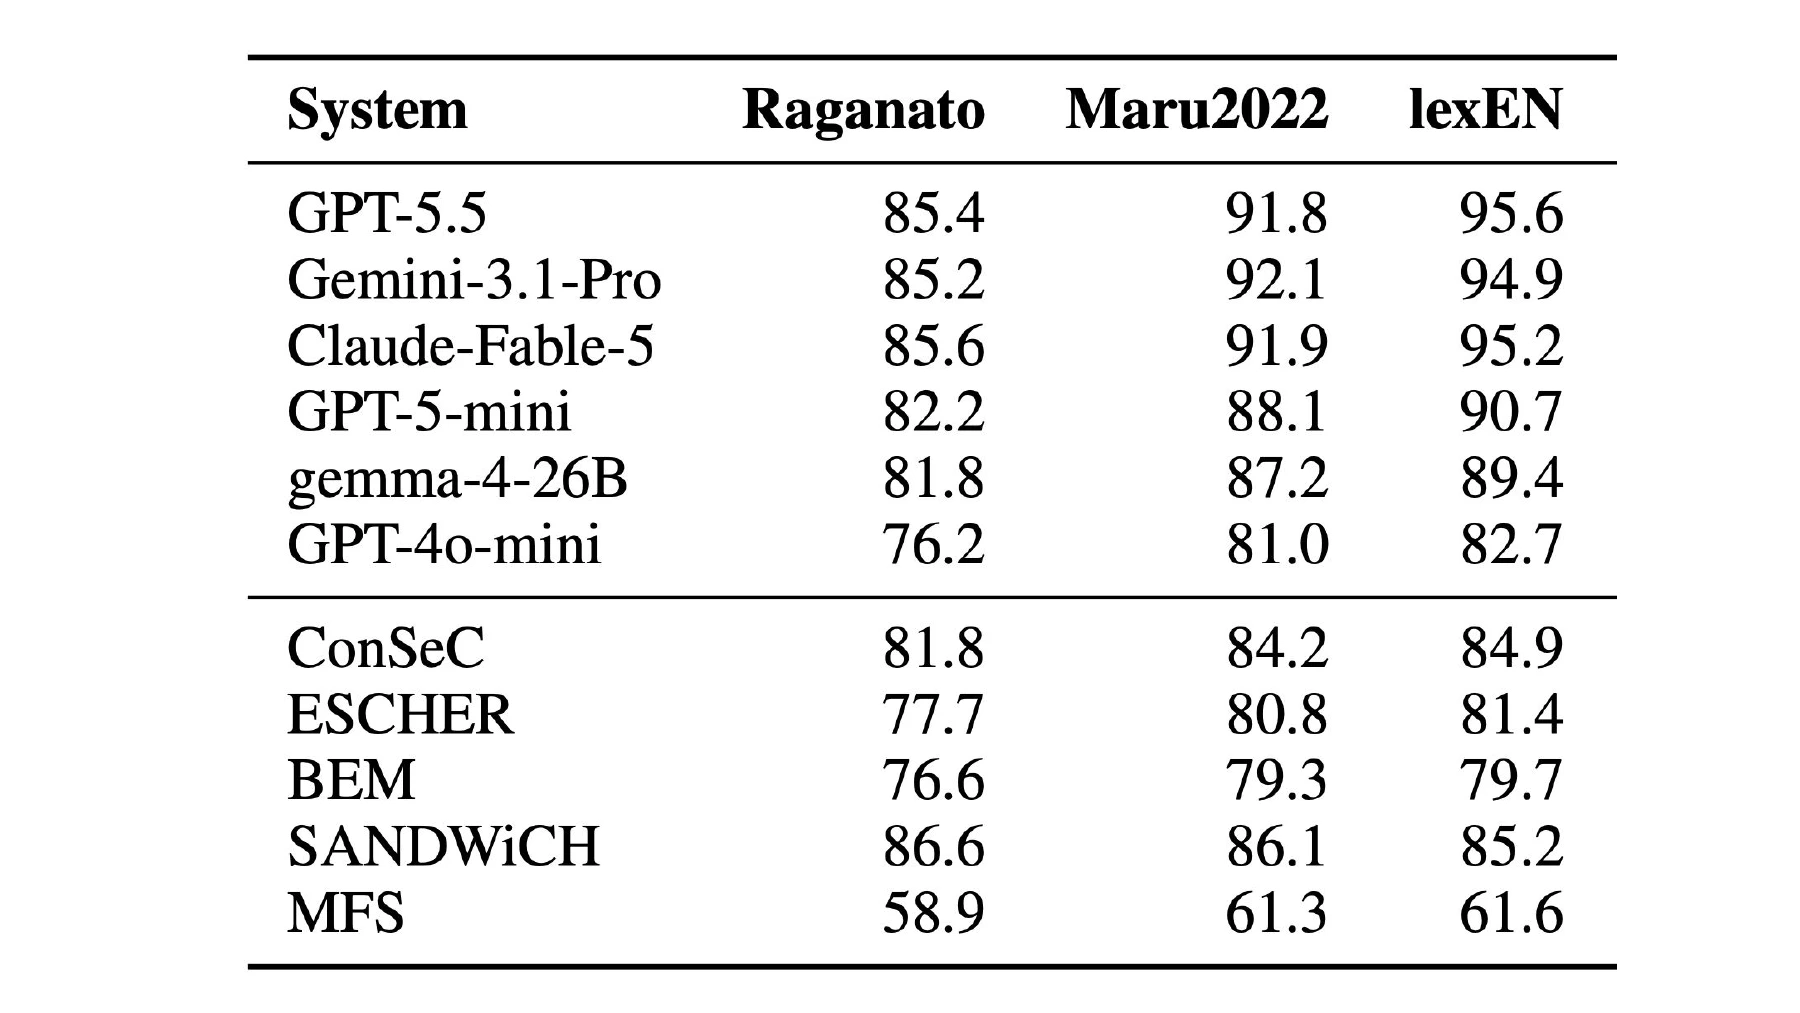
The strongest LLMs are around 95%, while the best traditional models are around 85%. The picture is very different. We had been judging the models against an answer key with mistakes.
So, for this particular task, LLMs are good. How close are they to the lexicographers themselves?
The lexicographers do not always agree with one another. Some distinctions are subjective, as you probably felt in the quiz. We compared their agreement with each other against the models’ agreement with them.
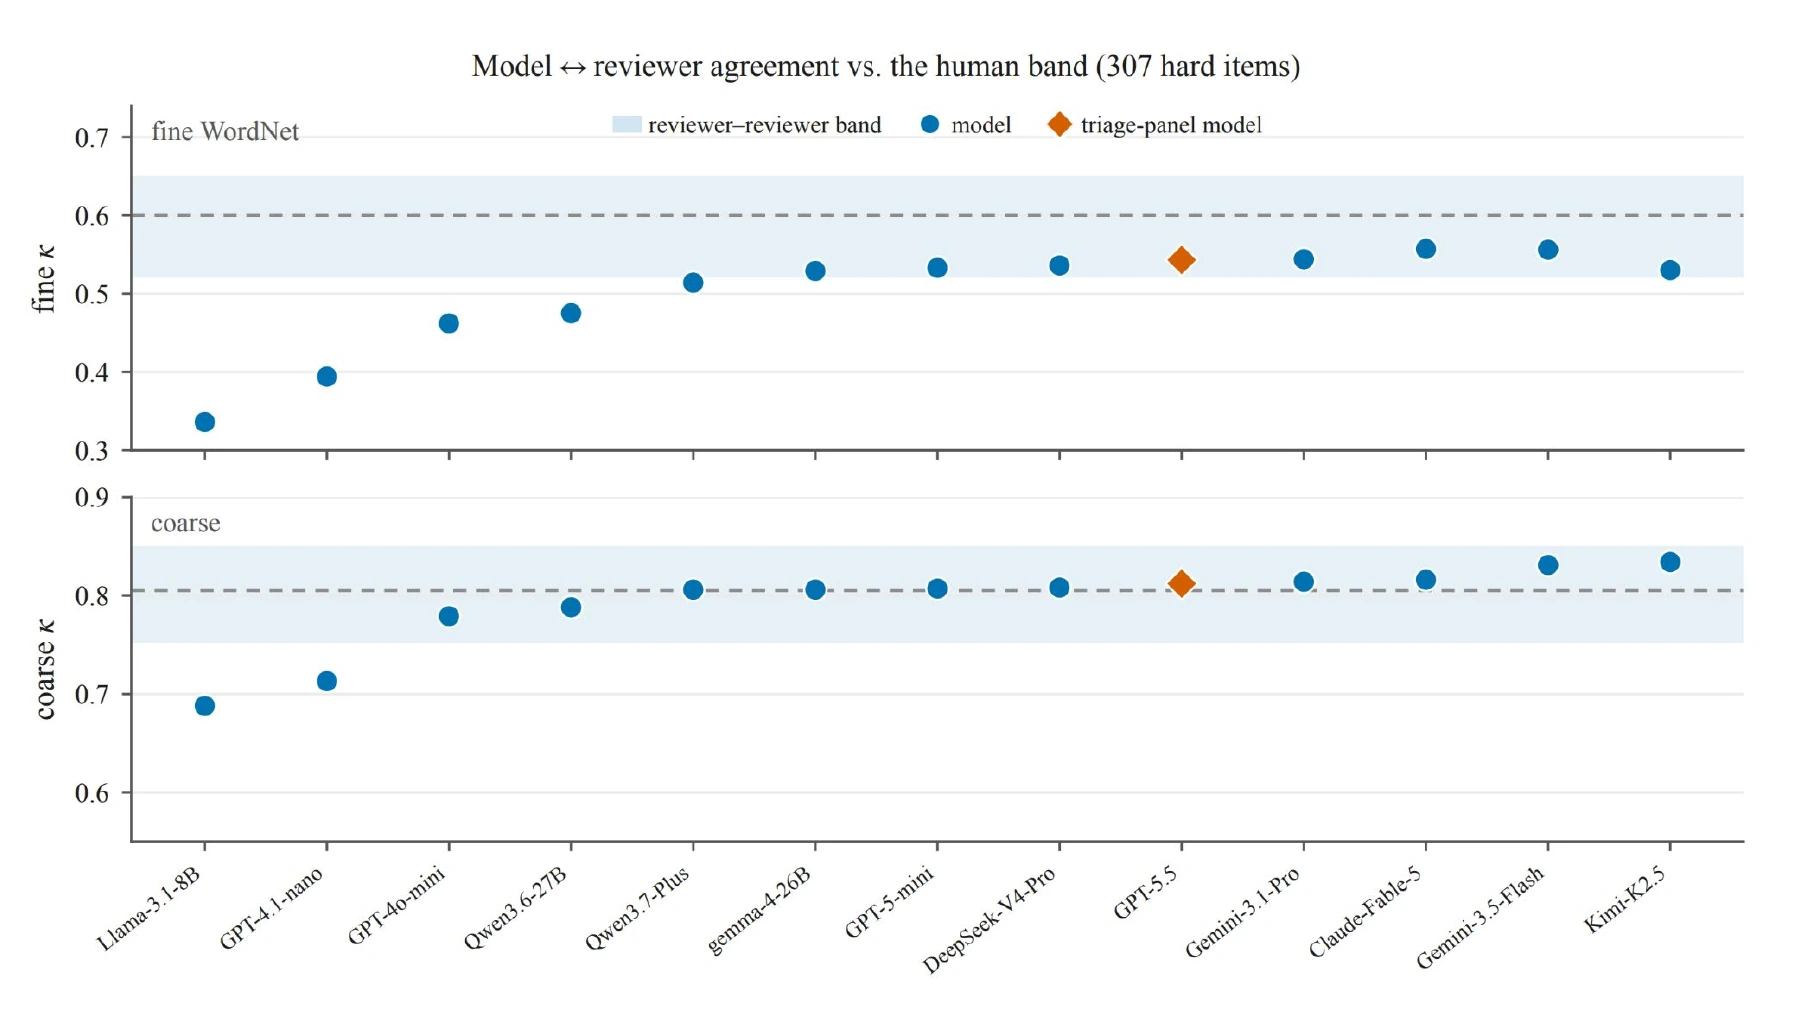
The strongest models come close to expert agreement when we group meanings more broadly. And remember, these are top lexicographers — there may be fewer than a hundred experts at this level in the world. At the finest dictionary distinctions, there is still a gap. This is a narrow task with candidate senses supplied, but the result gives us a good reason to take LLMs seriously as labelers.
Another test: can LLMs give us better training labels?
We can check how good LLMs are at this task in another way: use their labels to train smaller models and see whether the results improve. Remember the bi-encoder? To train it, we need what you did in the quiz, but at scale: sentences with words marked and an answer saying which meaning each word has.
SemCor is a standard dataset for this, with more than 200,000 labelled items. Models learn from those labels. But what if some of the training answers are wrong too?
We took the same SemCor questions and asked GPT-5.5 to produce new answers. Then we retrained the same model architectures, using the same training code. We changed the labels.
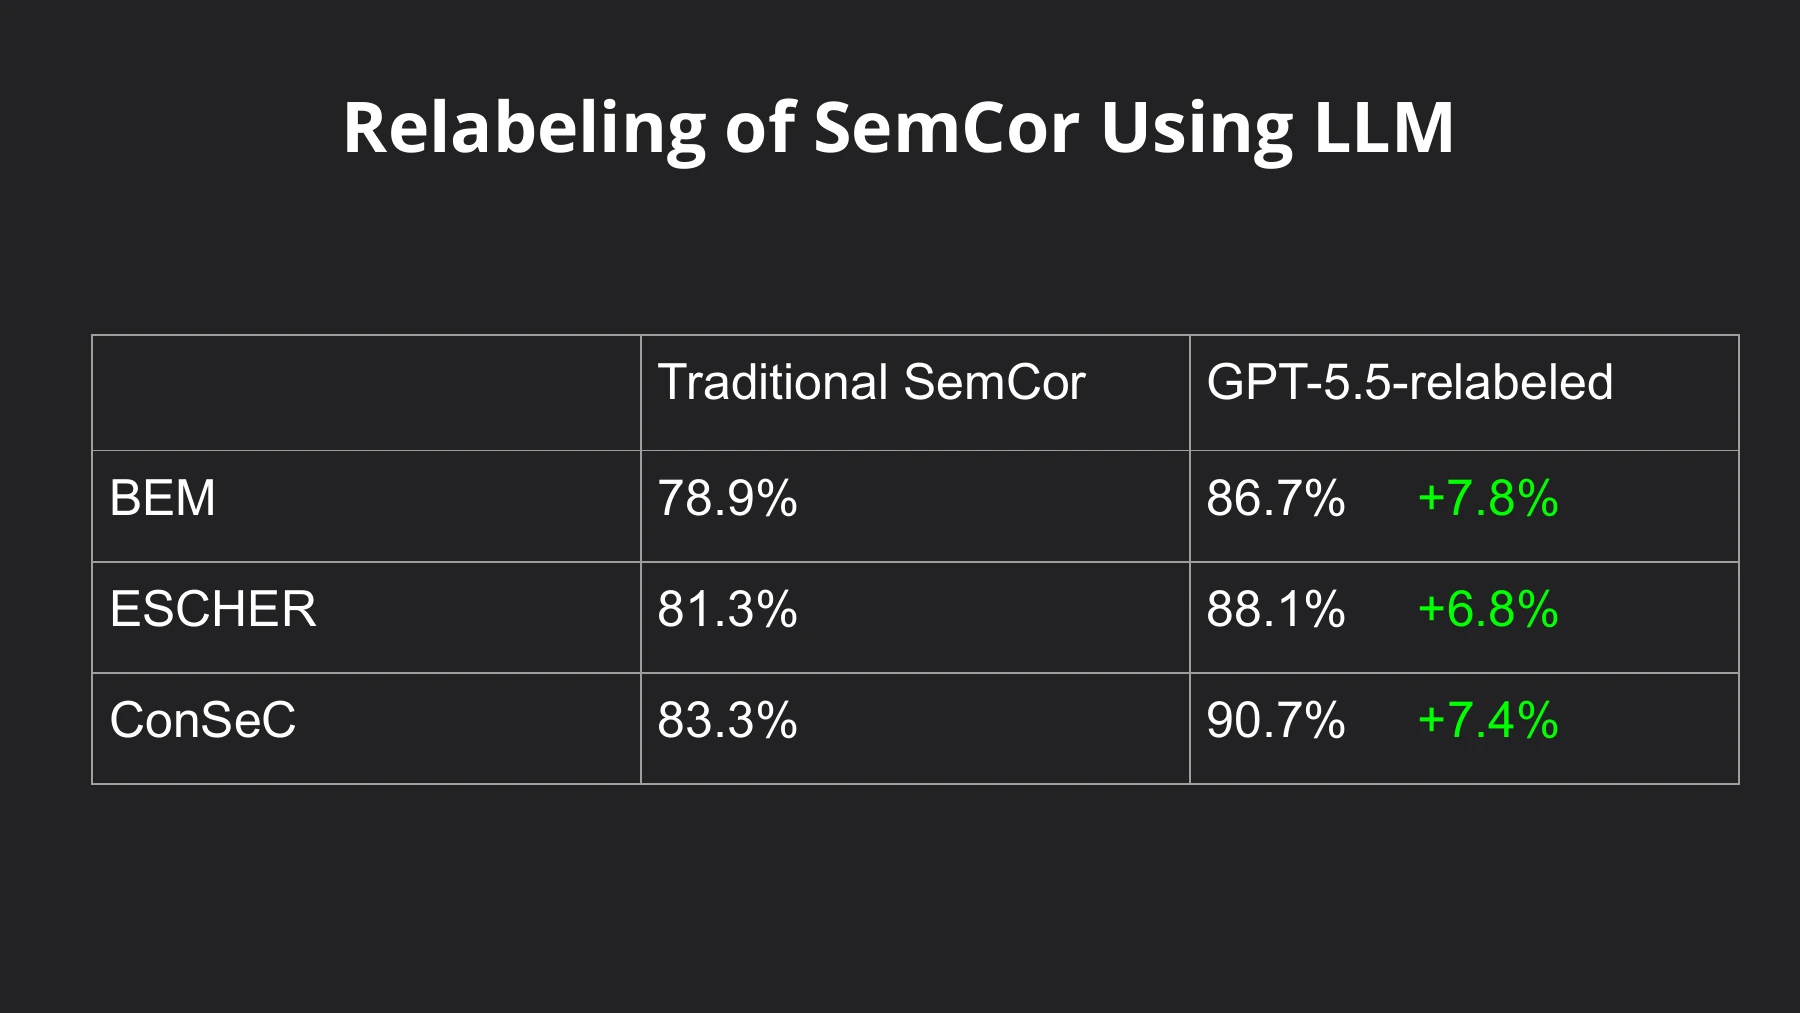
The scores went up for all three models.
I almost said “the corrected dataset”. I do not know that every new label is correct. Let’s call it the changed dataset. But changing those labels, without changing the training code, gave us substantially better results.
It is understandable that people make mistakes here. Imagine sitting down to label more than 200,000 items like the ones in our quiz. That is a lot of work.
And it gives us another use for a strong LLM: create the training labels, then use them to train a smaller model.
How much does that accuracy cost?
We also compared the models by price. You can explore the comparisons on the SenseBench leaderboard. The most accurate model in the comparison, GPT-6 Astra with extra-high reasoning, costs roughly $10,000 per million items — about one cent per decision.
Move to Gemini Flash and the cost is roughly ten times lower, with about half a percentage point less accuracy. Move further down to smaller LLMs, such as Luna and Gemma, and the price falls again. Gemma is surprisingly capable on this task, at around $10 per million items.
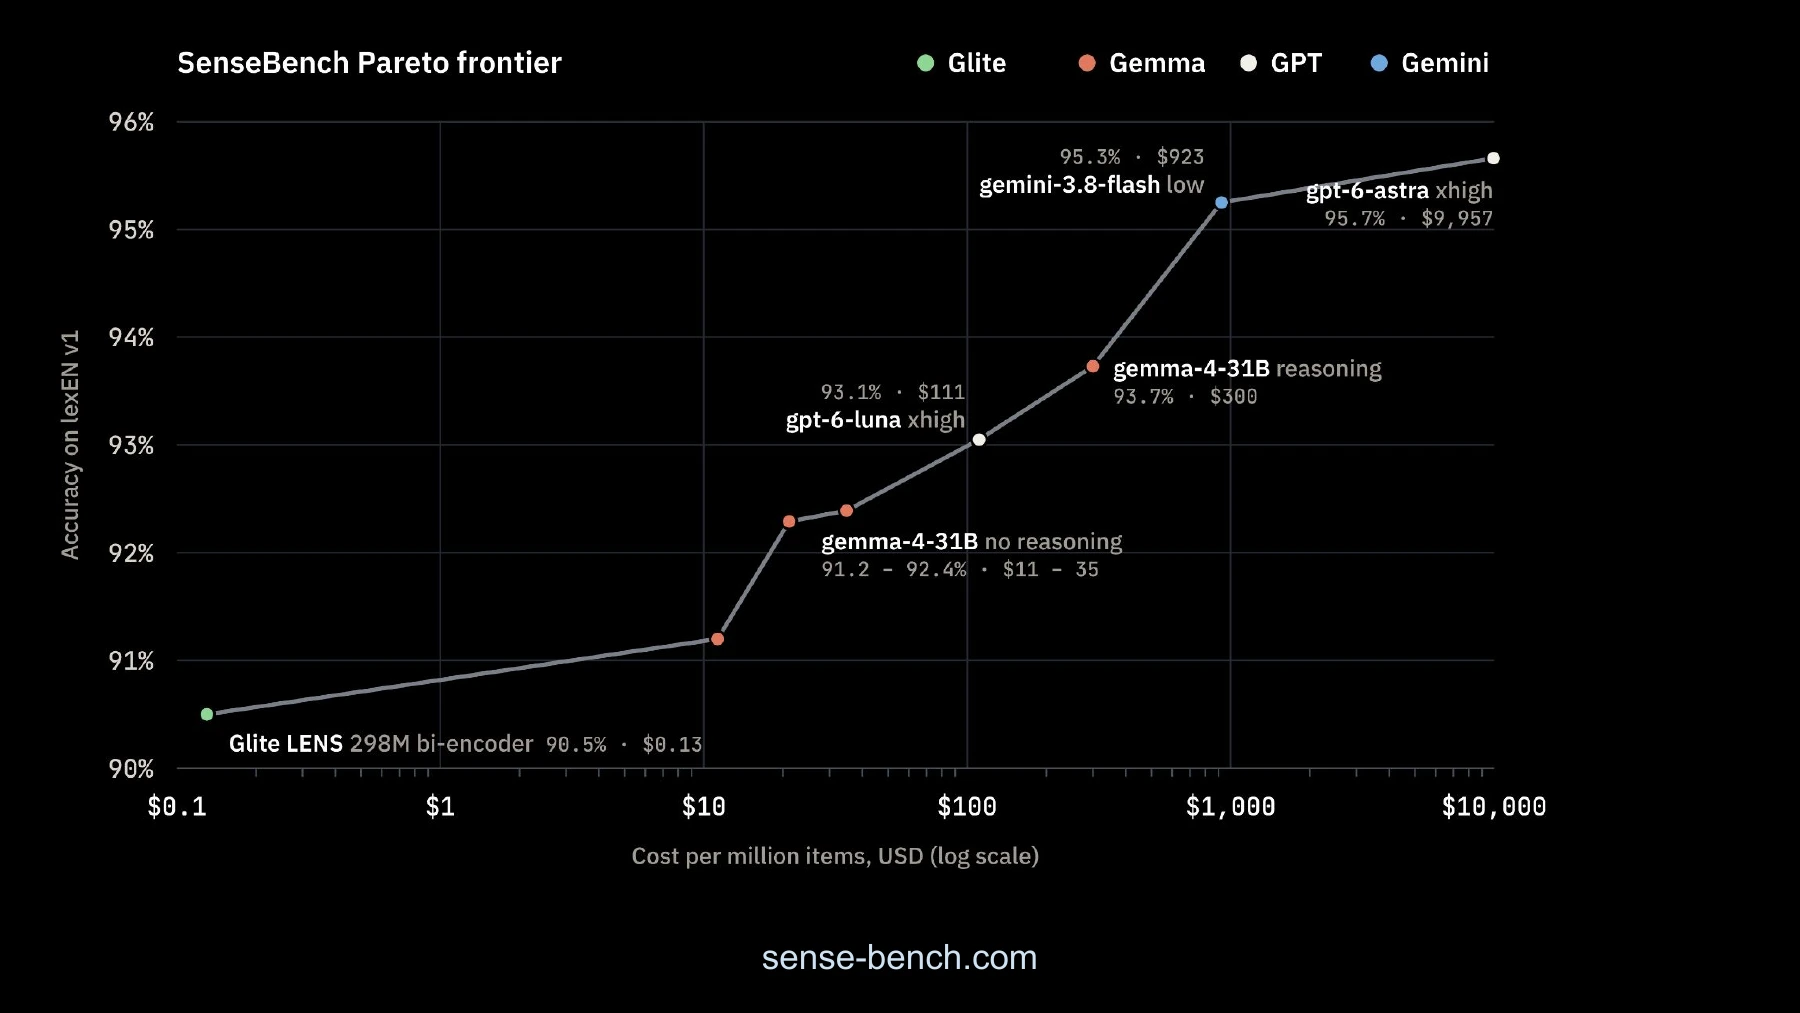
Then there are specialised models, at around ten cents per million items. Cheap LLMs are much cheaper than expensive LLMs. Specialised models are much cheaper again.
Does that matter? Why not just pay a little more for the best answer?
If we are evaluating a small test set for a paper, accuracy may be the main concern. If we are building a product, we need to know how much we can afford to process. Let’s give those prices some scale.
What would it cost to process 37,000 movies?
In our app, you can enter a movie name and find the words, meanings, idioms and phrasal verbs you need to learn. We have a little under forty thousand movies processed.
What would you guess it costs to process that collection?
The 37,000 movies in this estimate contain about 200 million words. With a top LLM, the bill is around $1 million. With a cheap LLM, about $2,000. With a bi-encoder, $26.
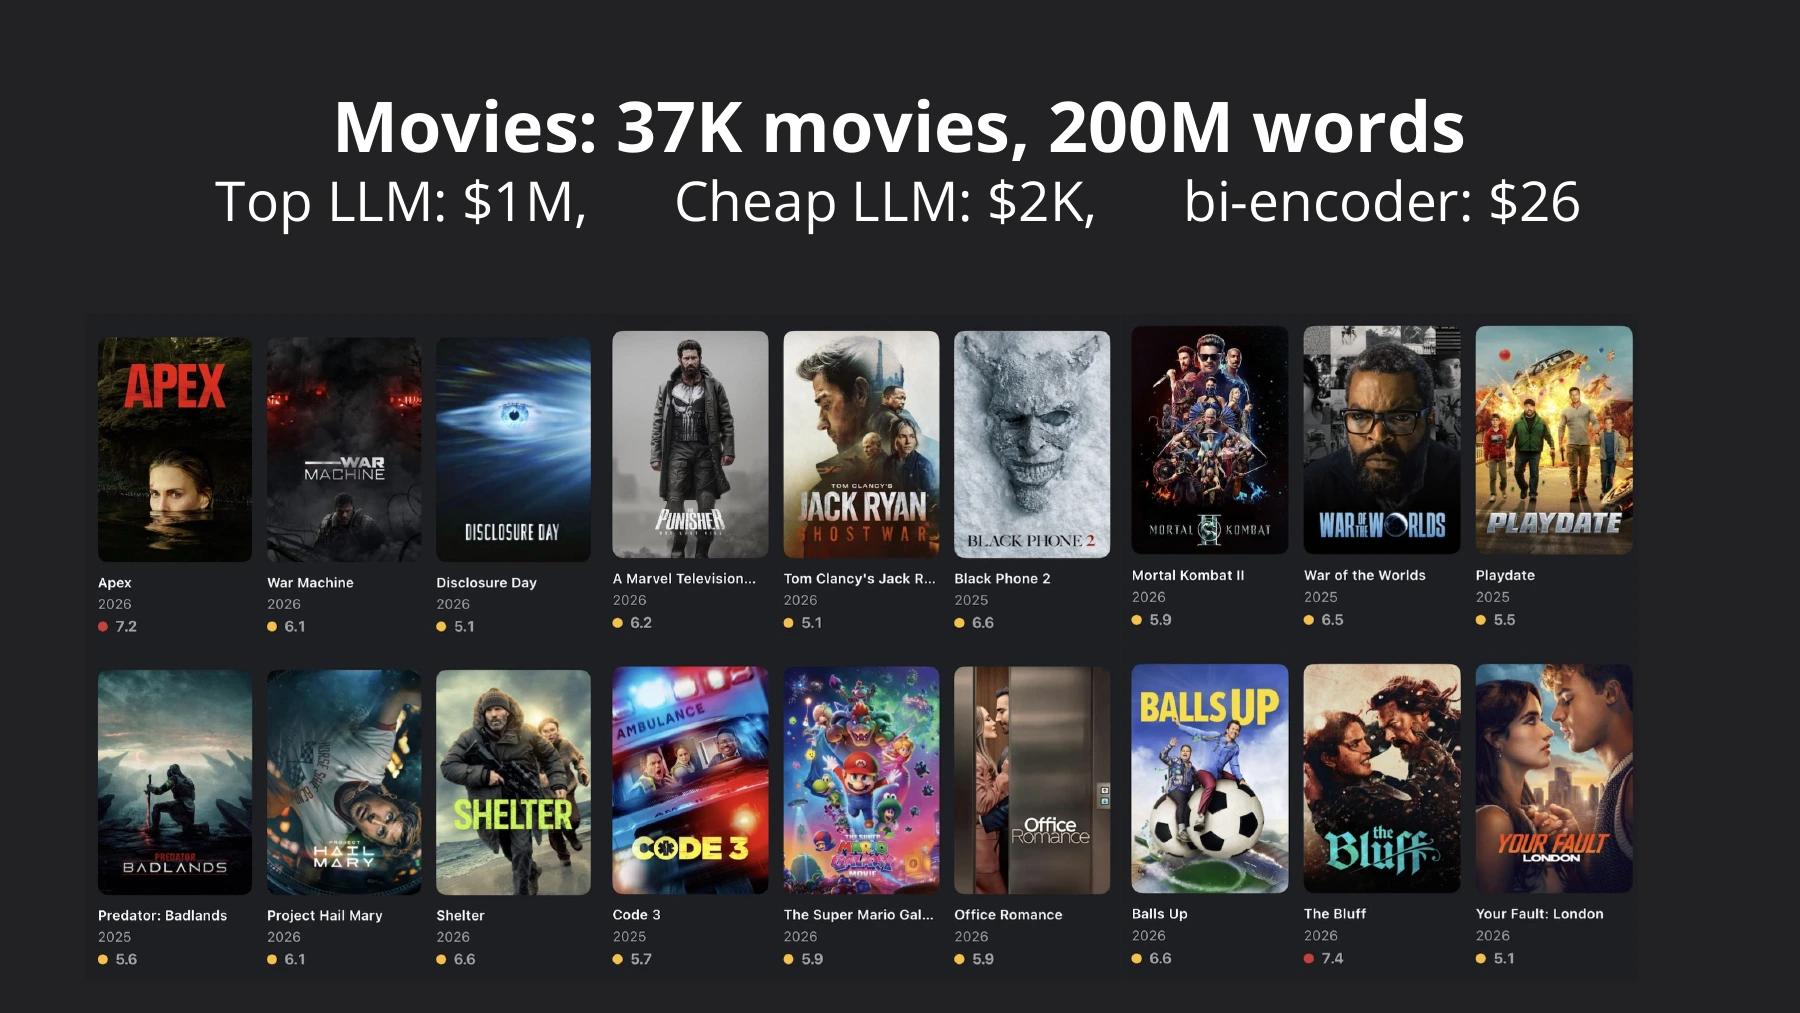
That is the difference behind a feature that looks simple: type in a movie name and see what you do not know. We extract the concepts, then use the Knowledge Prediction model to estimate which ones are missing for you.
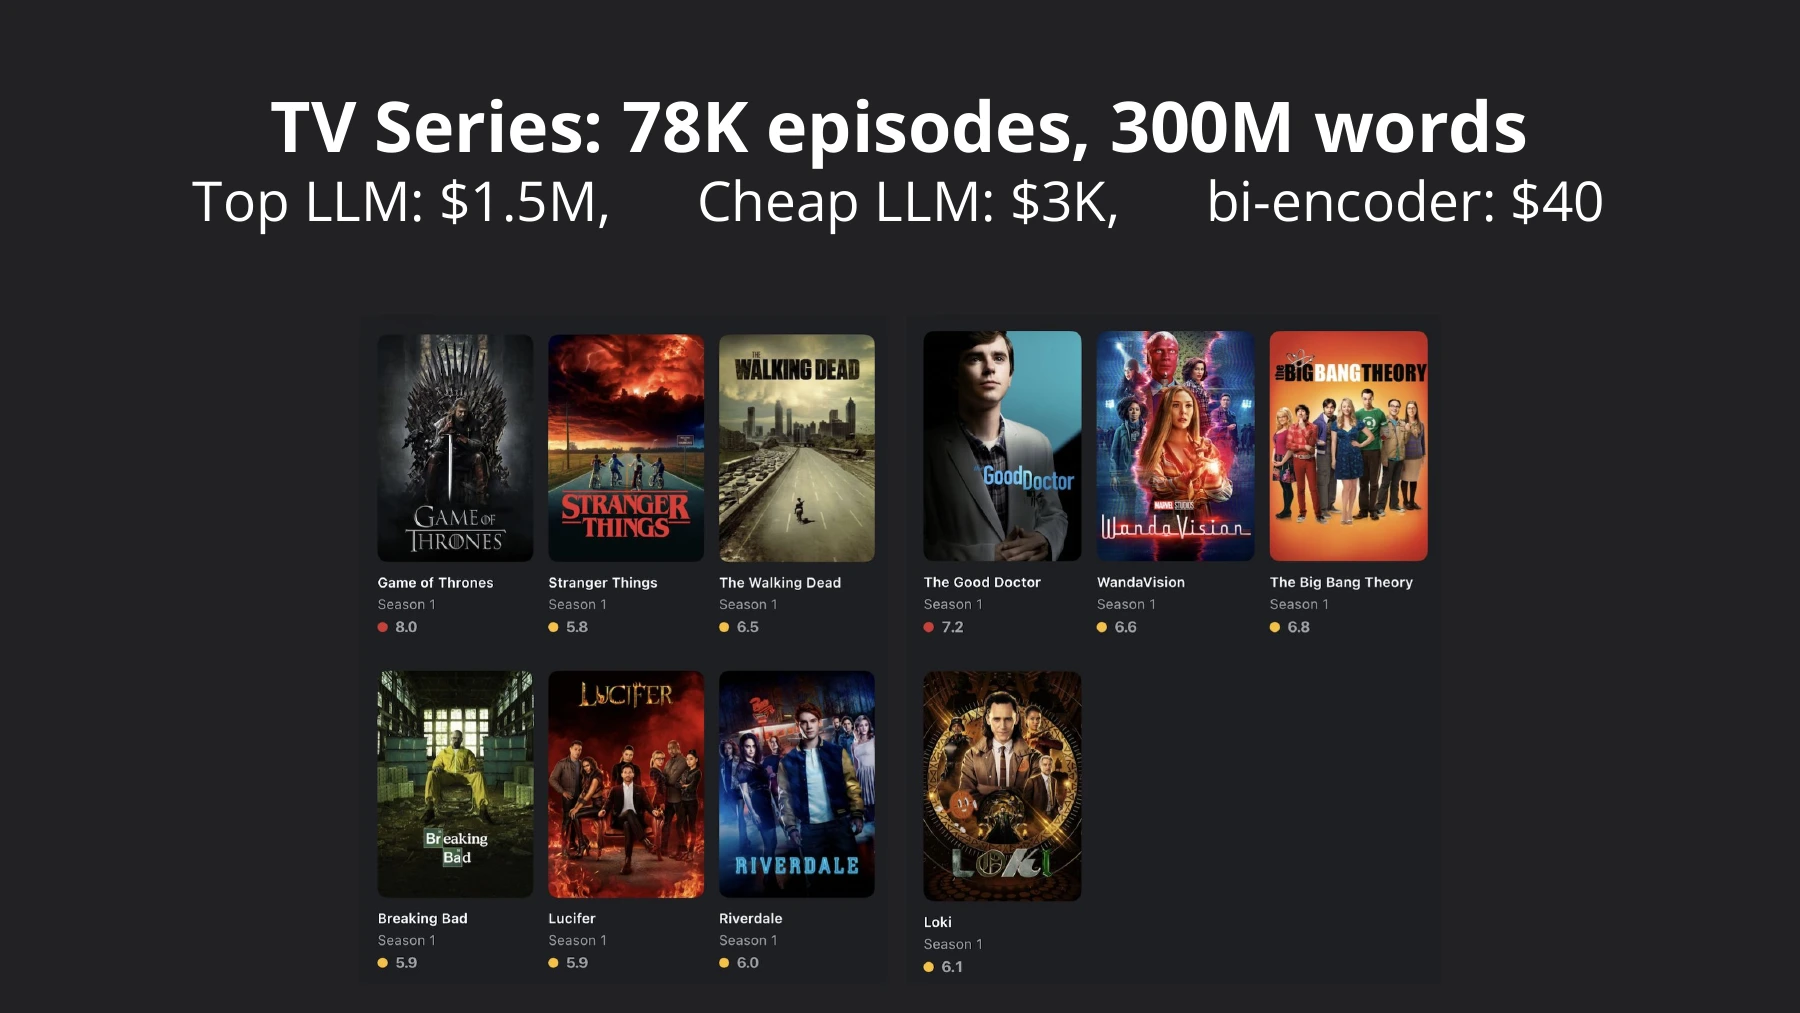
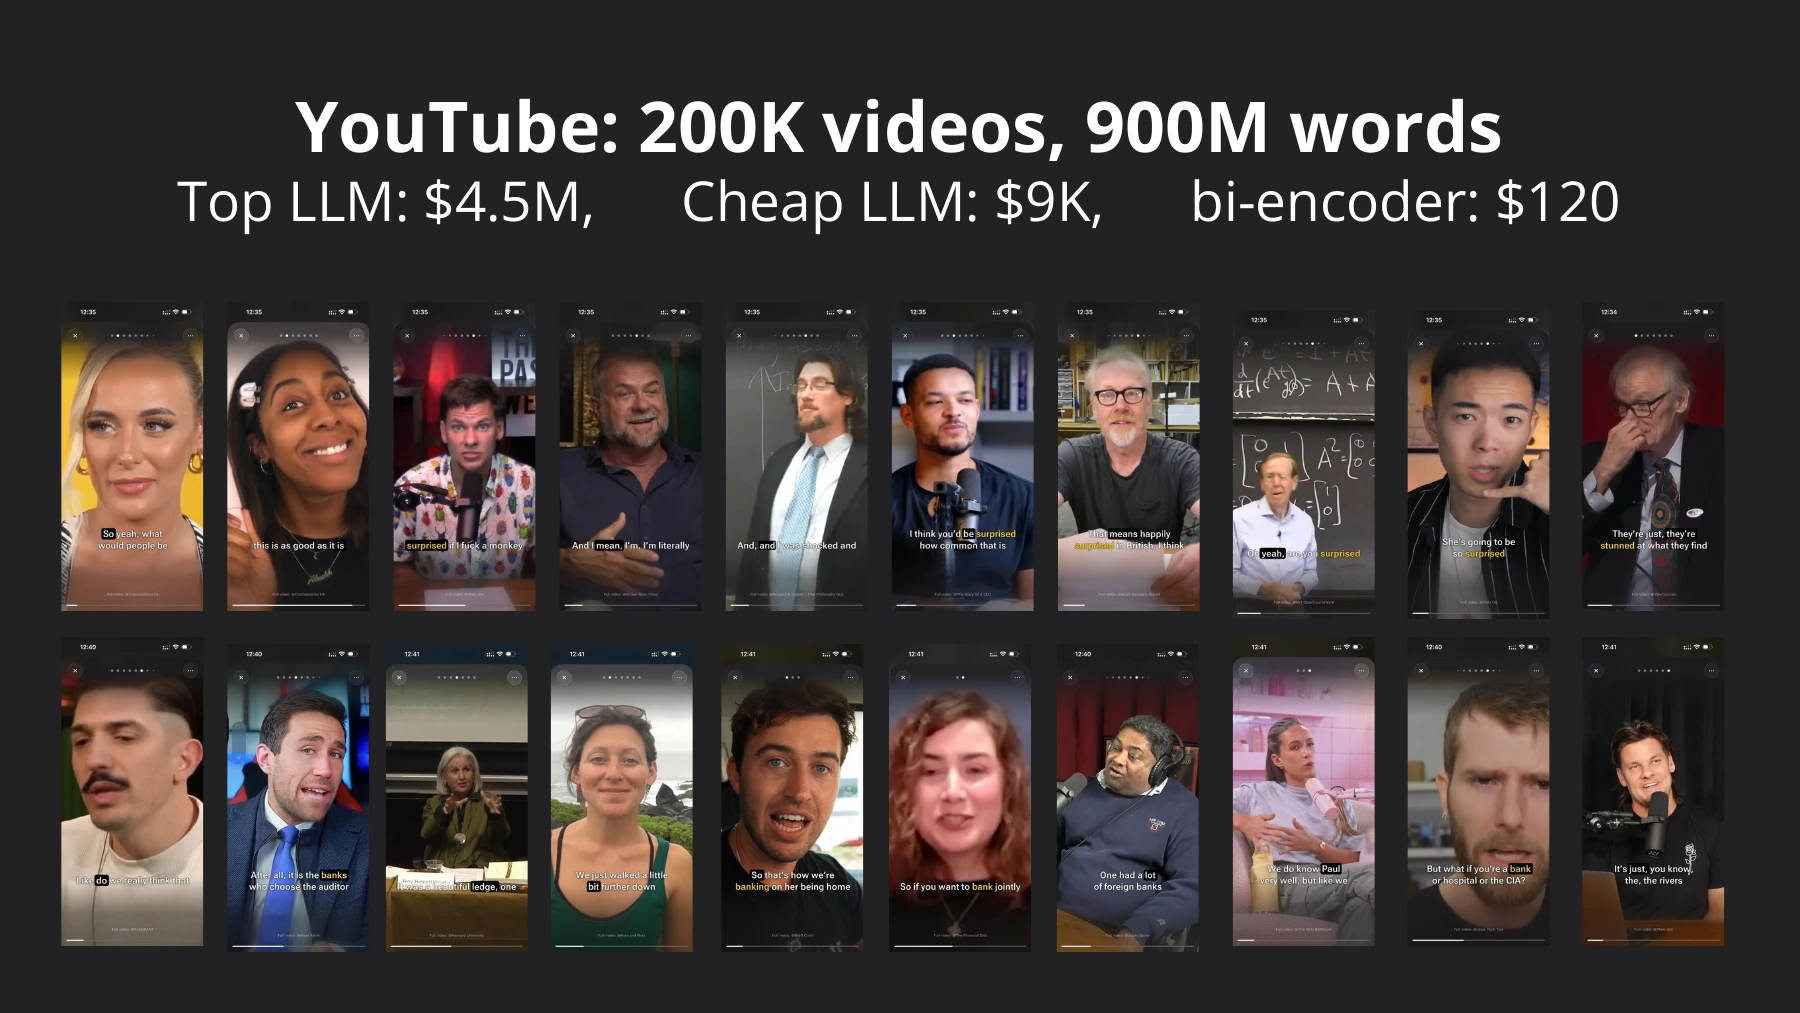
What comes next? TV series: 78,000 episodes and about 300 million words. Then YouTube, which we process to find examples of how people use a particular meaning. The 200,000 videos here contain about 900 million words.
Then songs: about two billion words in this collection. The song feature is nice because you can connect Spotify or Apple Music, find the songs in your playlists and learn the meanings and idioms you do not know. If you are not a native speaker, you can finally understand the songs you listen to anyway.
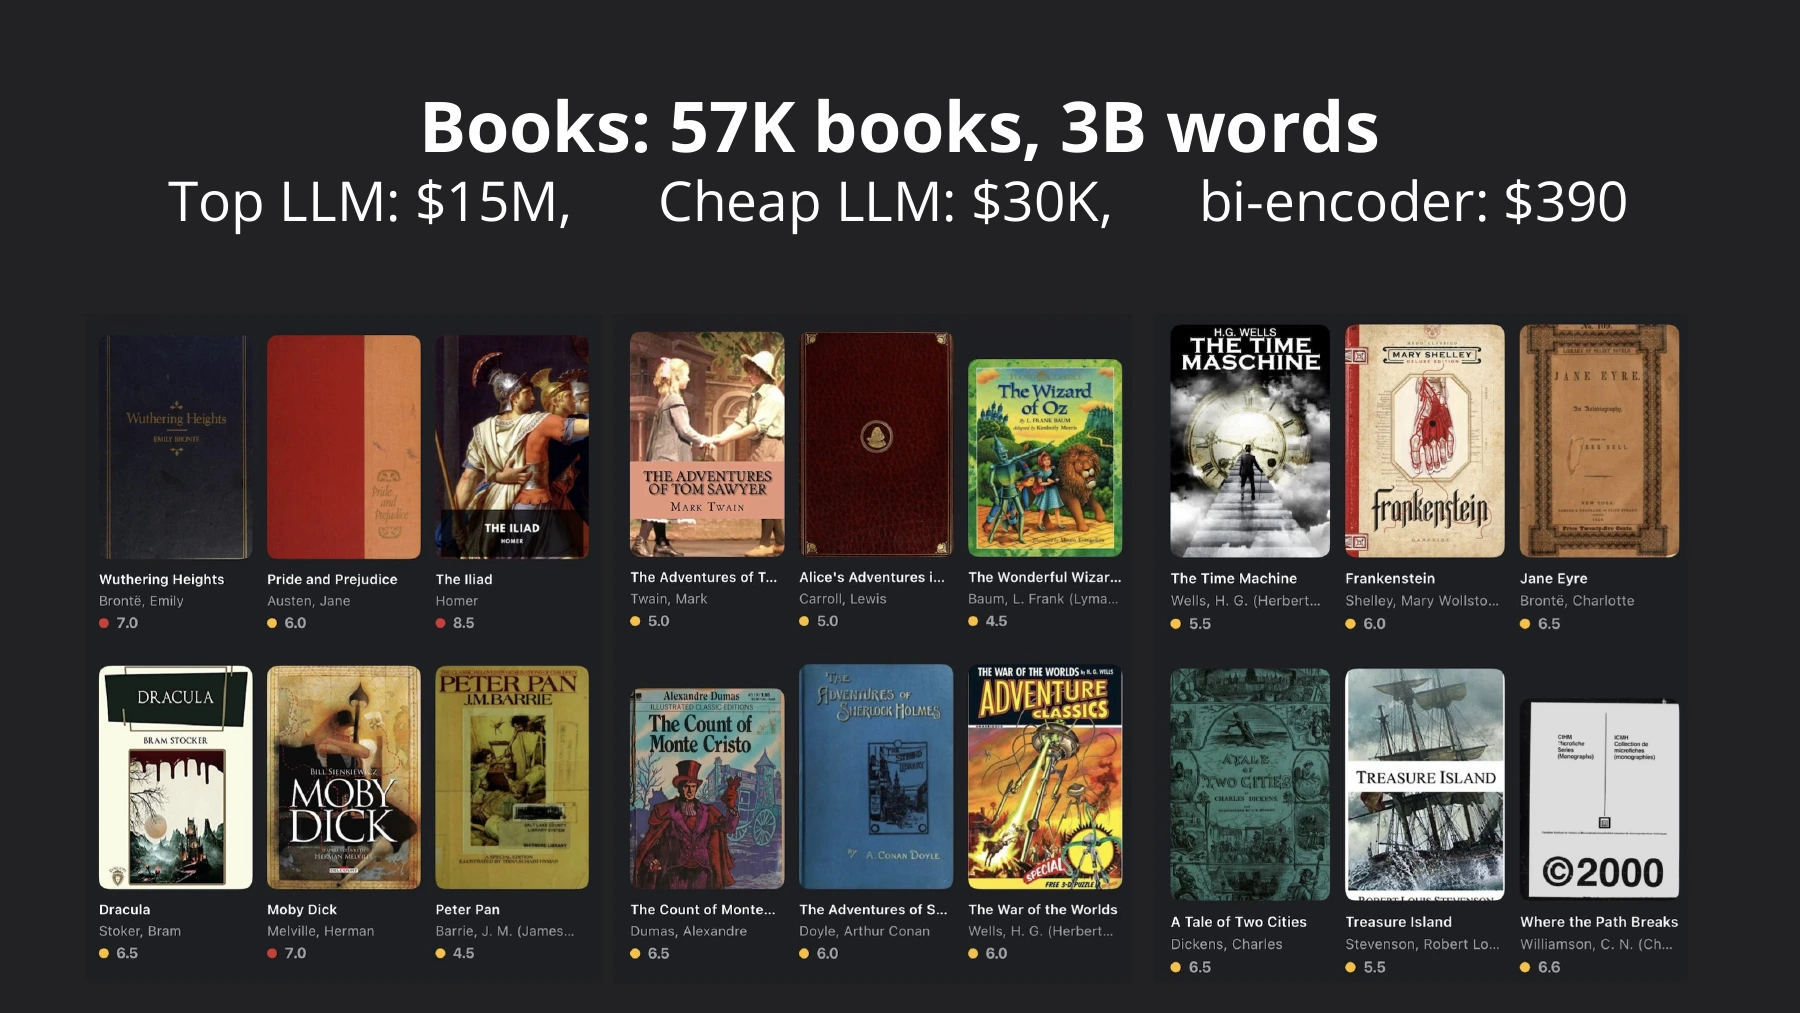
Books take us further: 57,000 books, with about three billion words. Now the top-LLM estimate is $15 million. Even a cheap LLM is $30,000. The bi-encoder is still affordable.
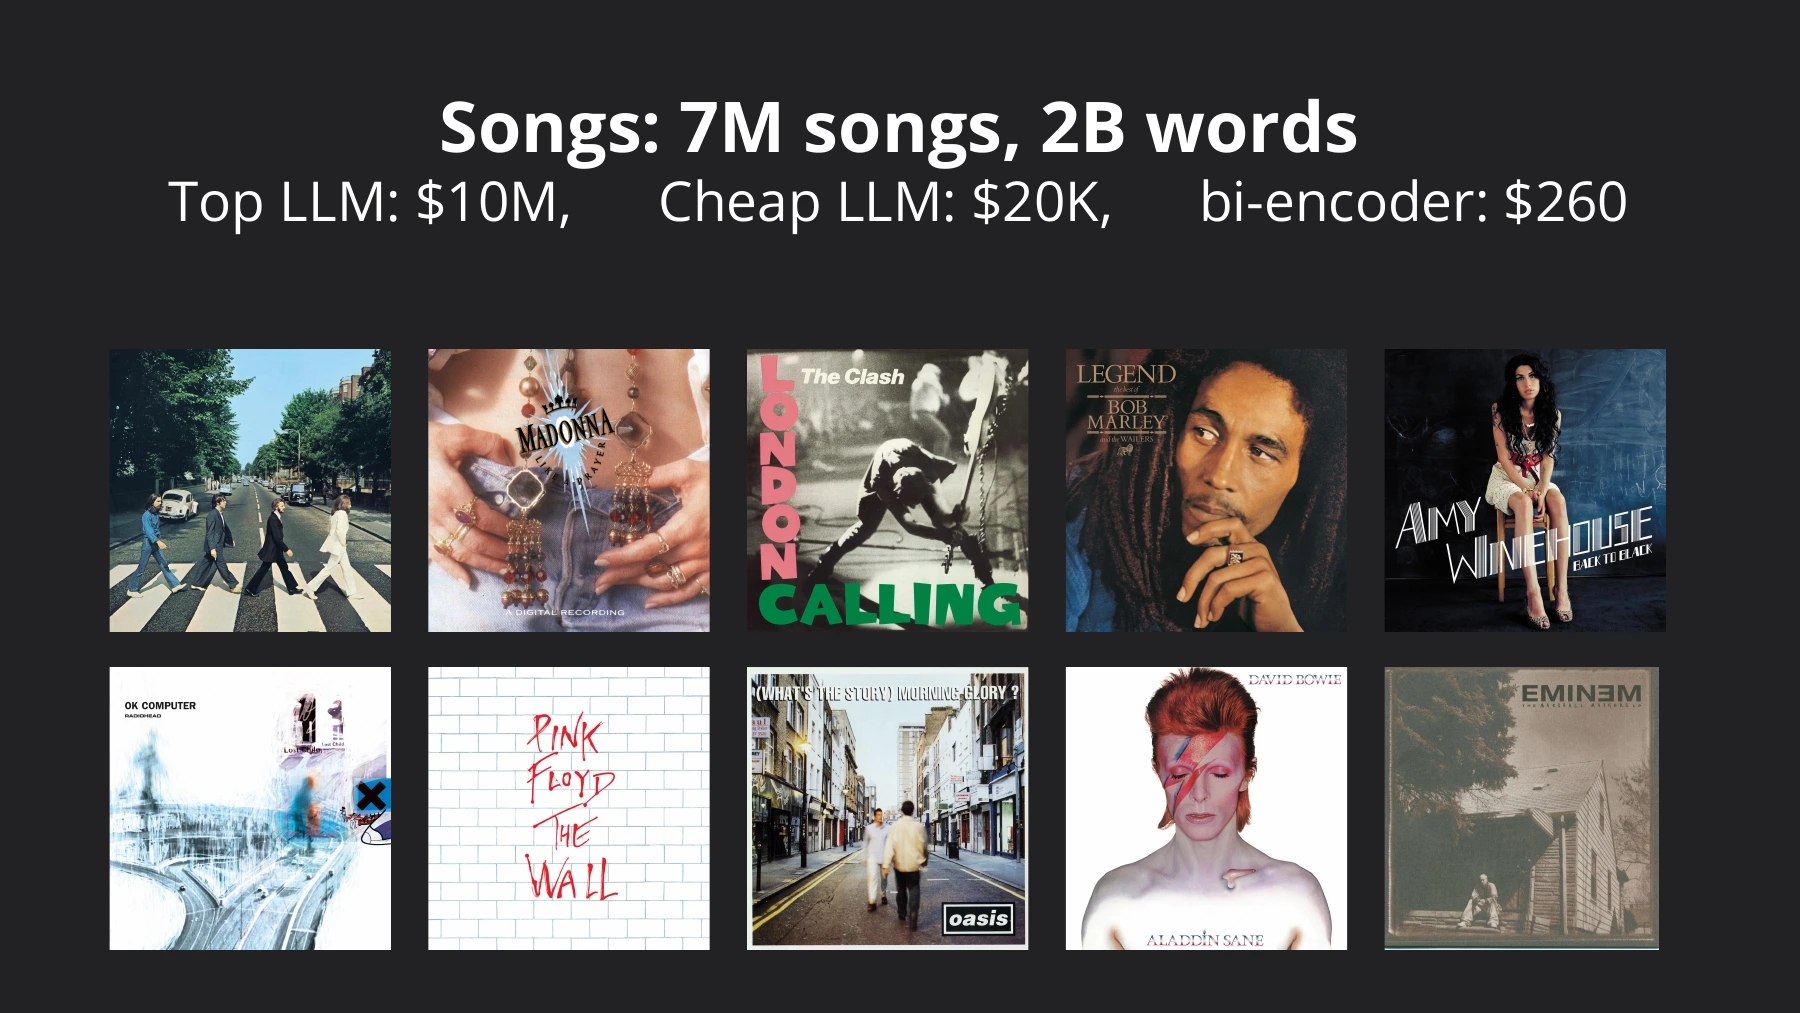
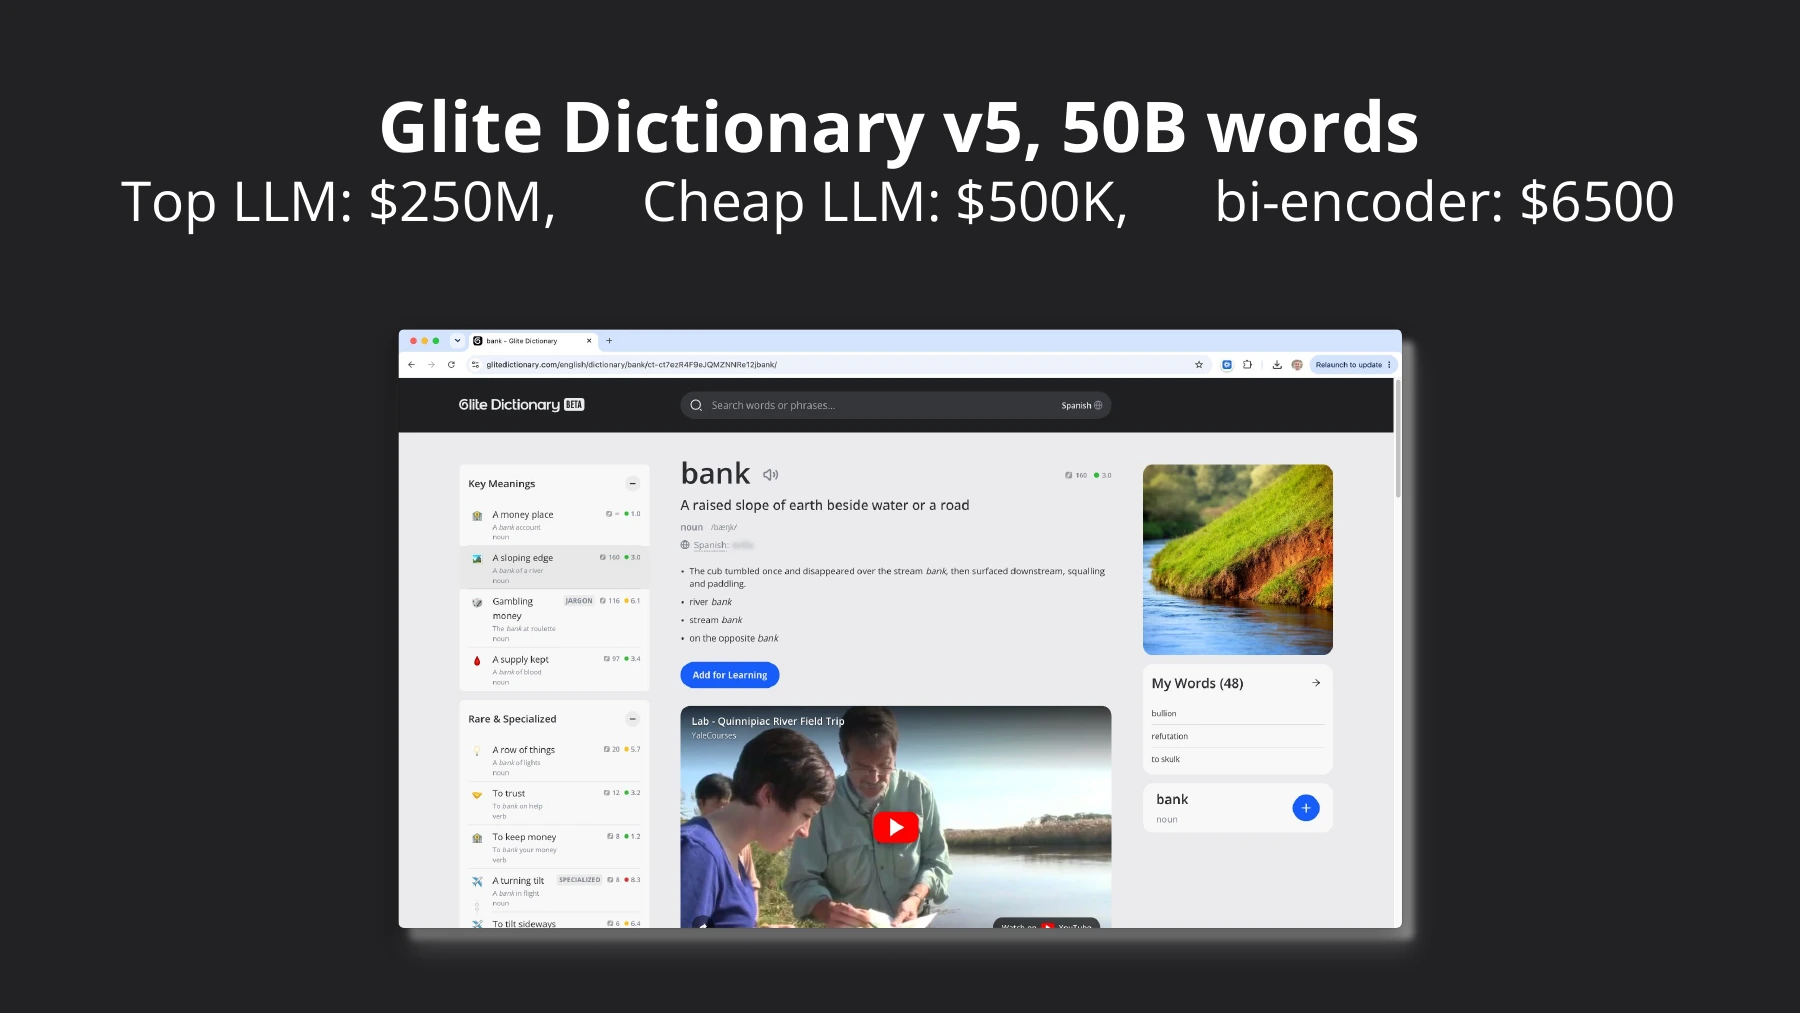
And we can go further still. We are building our own English dictionary. To get good coverage of different senses, we work with a collection of roughly fifty billion words.
Even the cheap-LLM estimate is now half a million dollars. A bi-encoder is about $6,500.
The strongest LLMs are very capable at these tasks. The problem is the cost at this scale. Maybe in two years the prices will have fallen enough that we simply use them and forget about some of this engineering. But today, the difference matters.
And what if the work arrives every day?
Movies and songs are expensive to process, but in principle we only need to do it once. Until we have a new version of the knowledge graph. Then we do it again. And then another version. But theoretically, once.
Student work is different. New tasks, new answers, new homework. If we want to find mistakes, we have to keep processing it.
From watching my sons do their homework, I’d say a typical task takes about two to five minutes. It can involve ten to fifty concepts — even one mathematical equation can require several different rules.
That gives us roughly 100–1,000 concept instances per student-hour. At the top-LLM rates used in this estimate, extracting them costs around $0.50–$5.
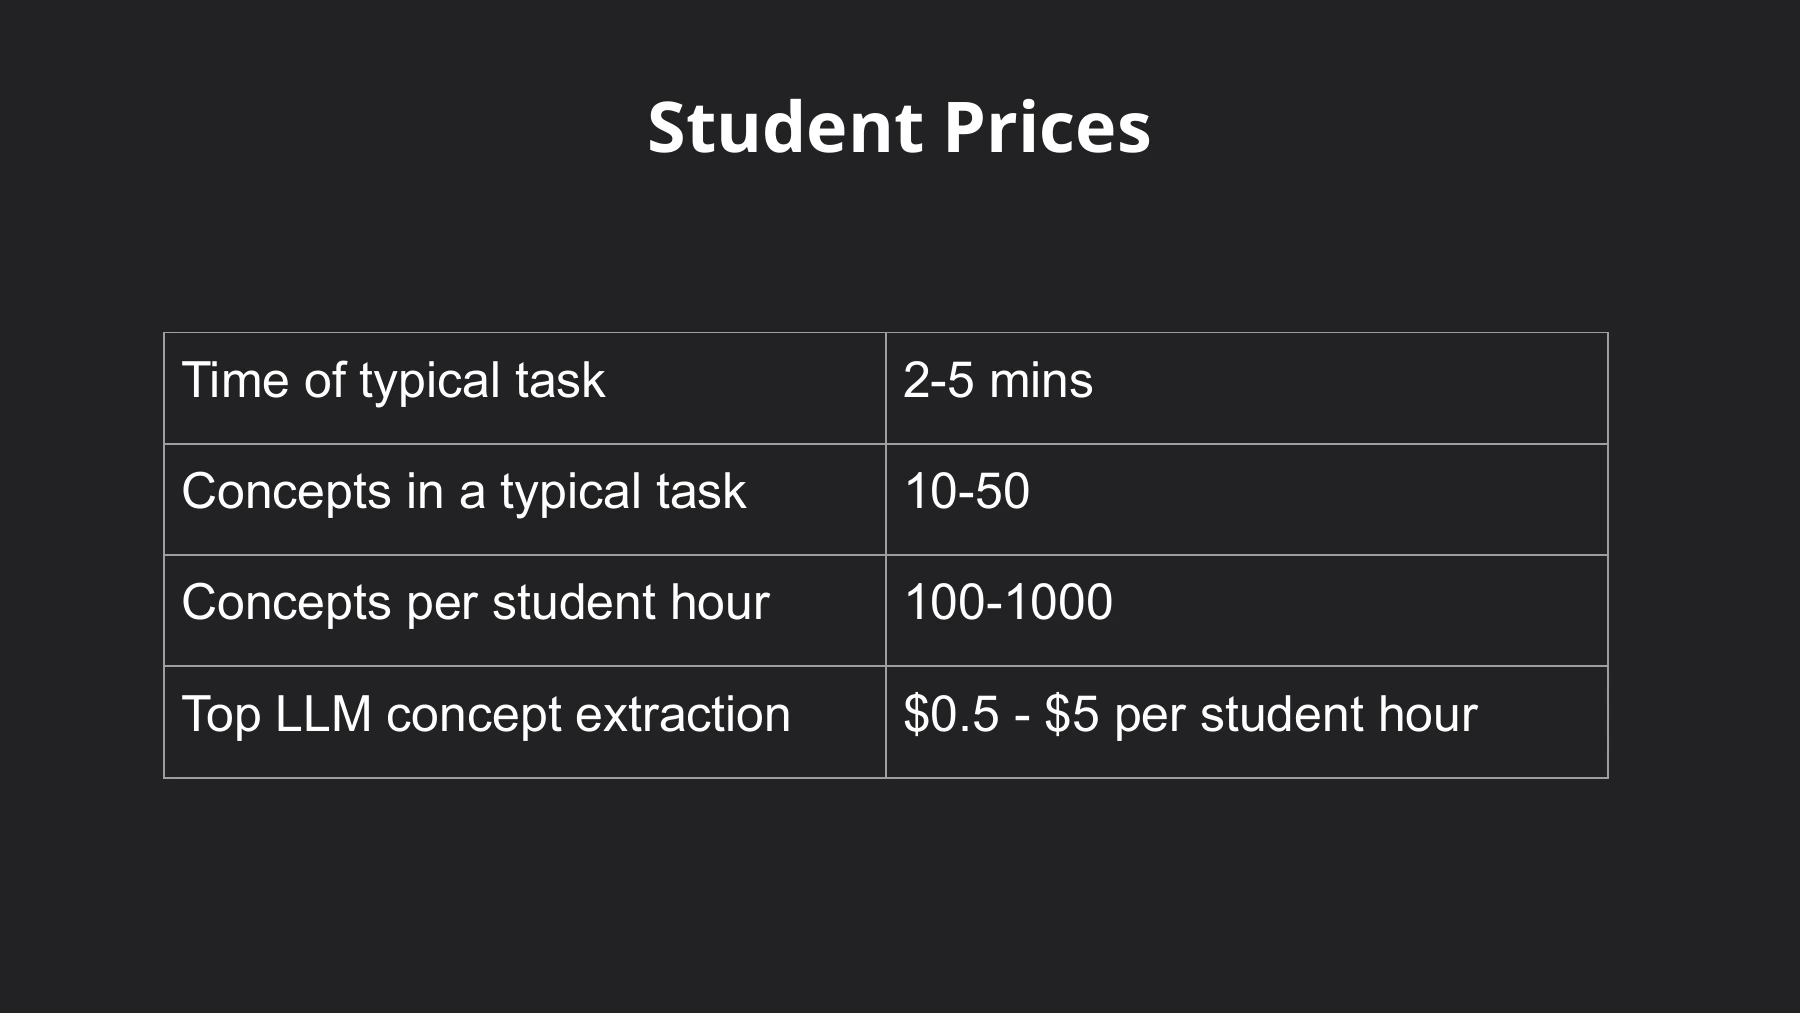
For thirty students doing an hour of homework, that becomes $15–$150. Now it is a substantial cost for a classroom. We need a way to do this more cheaply.
Does the same approach work in mathematics?
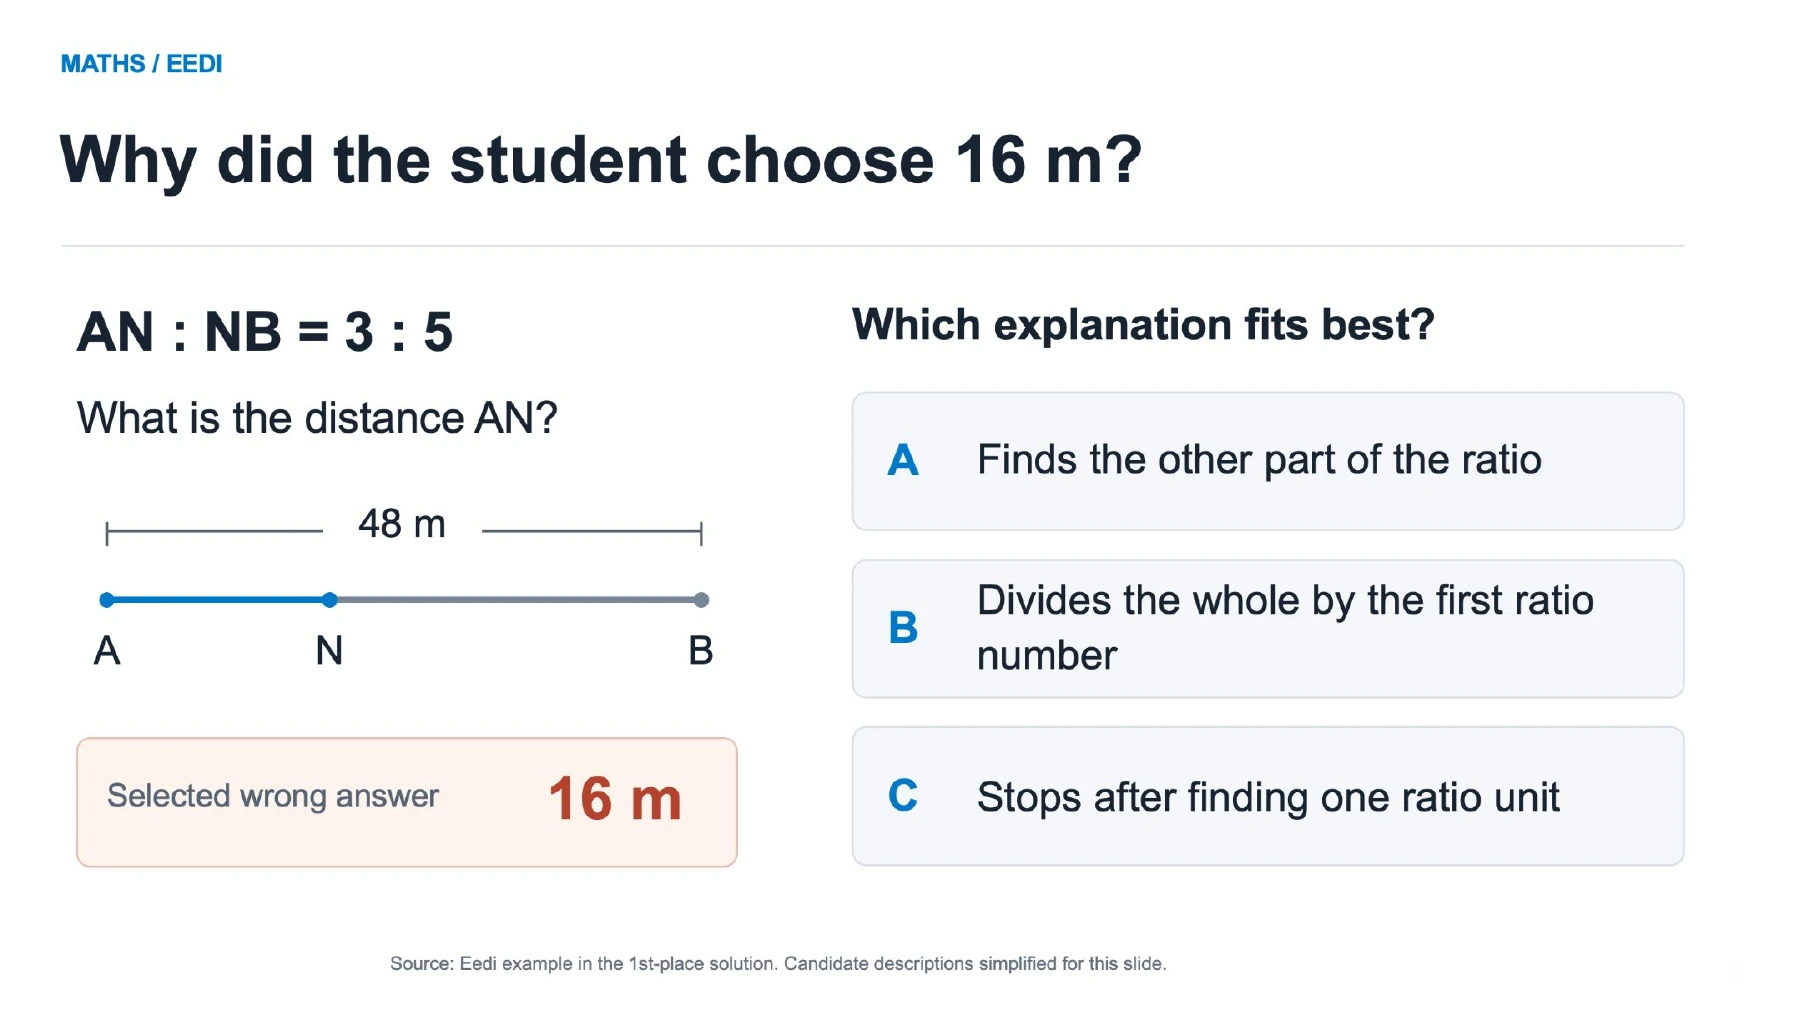
So far, most of the examples have been about language. Eedi’s Kaggle competition asked a related question in mathematics: given a student’s wrong answer, what misconception might explain it?
Here is the kind of problem we mean. The student chooses 16 metres. We want to identify the misunderstanding behind that answer.
A useful thing about a Kaggle competition is that many teams try different solutions, and we can compare them on a leaderboard. The first-place solution here used essentially the hybrid architecture we have just discussed. Its code is available on GitHub.
A retriever first found a few dozen likely misconceptions. Then fine-tuned LLMs ranked the candidates in stages: down to eight, then five, then a final ranking of those five.
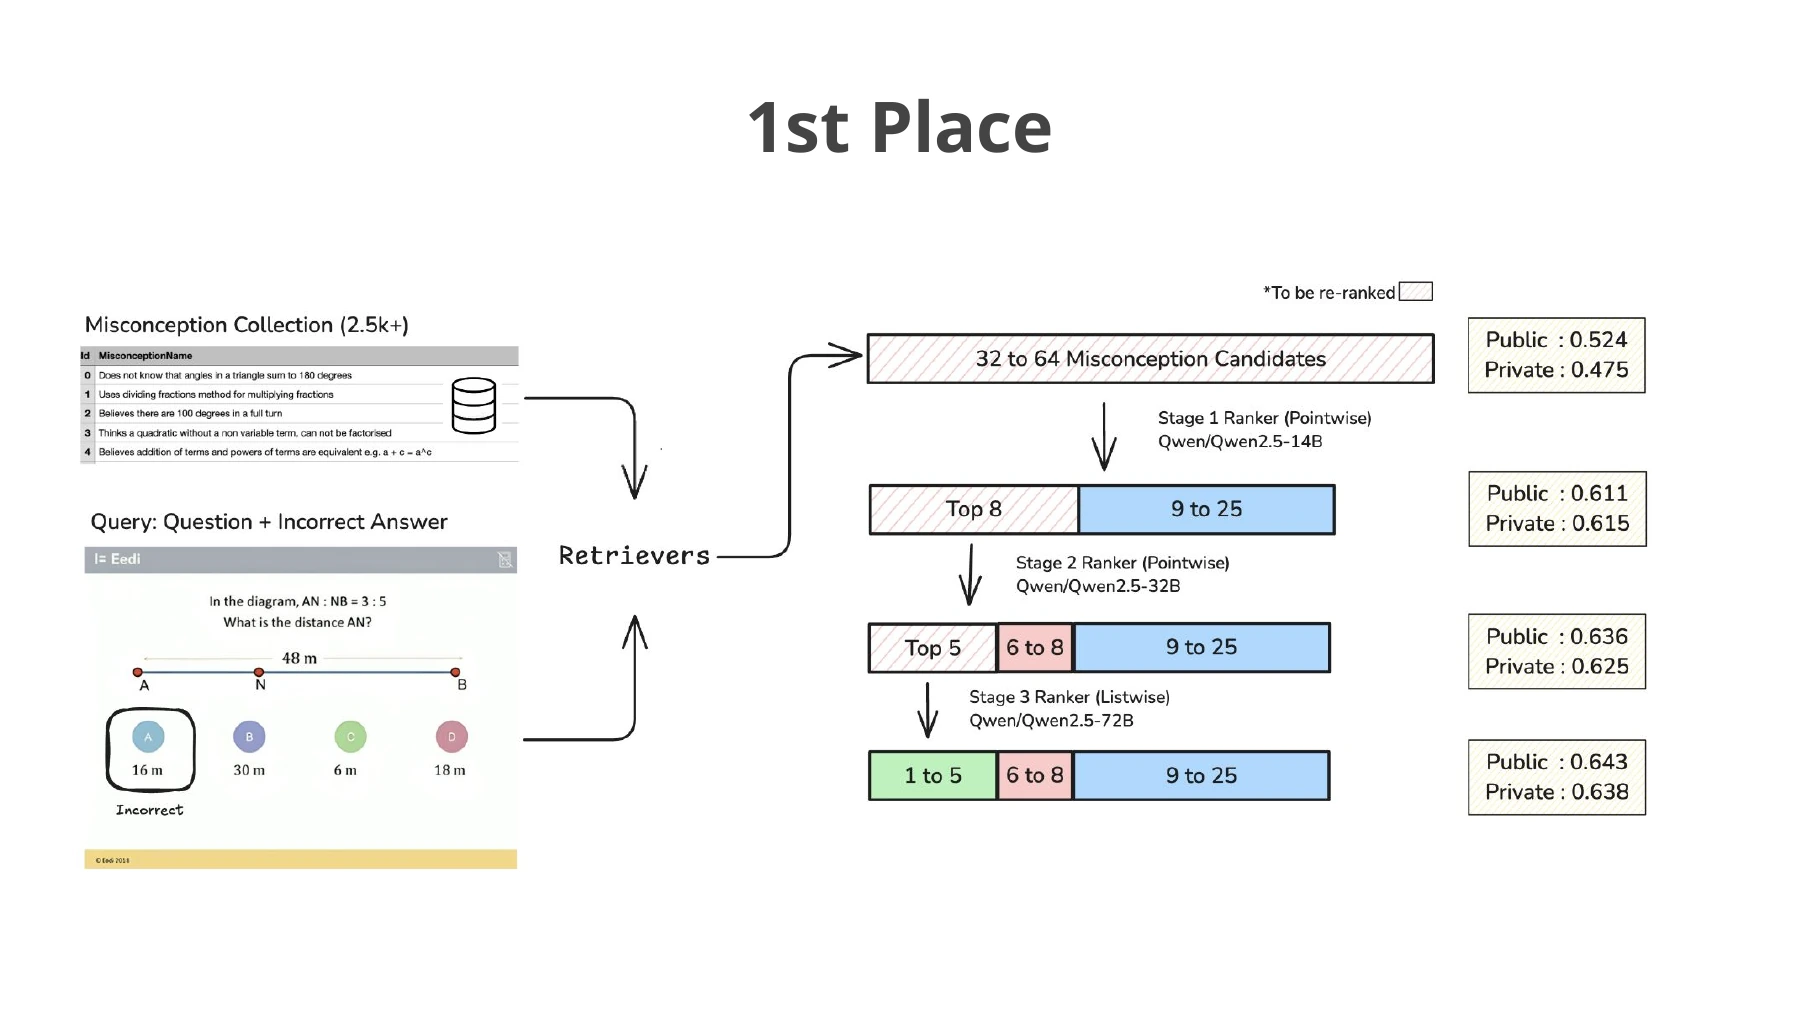
The expensive models work on an increasingly small set of possibilities. The same basic idea carries over from word meanings to misconceptions in maths.
So what is the practical recipe?
If you need a concept extractor, you can build it with encoders or with LLMs.
With encoders, train one to encode the text and another to encode your concept definitions. Find the most similar concept vectors. If you need a closer comparison, add a cross-encoder to rank the candidates you retrieve.
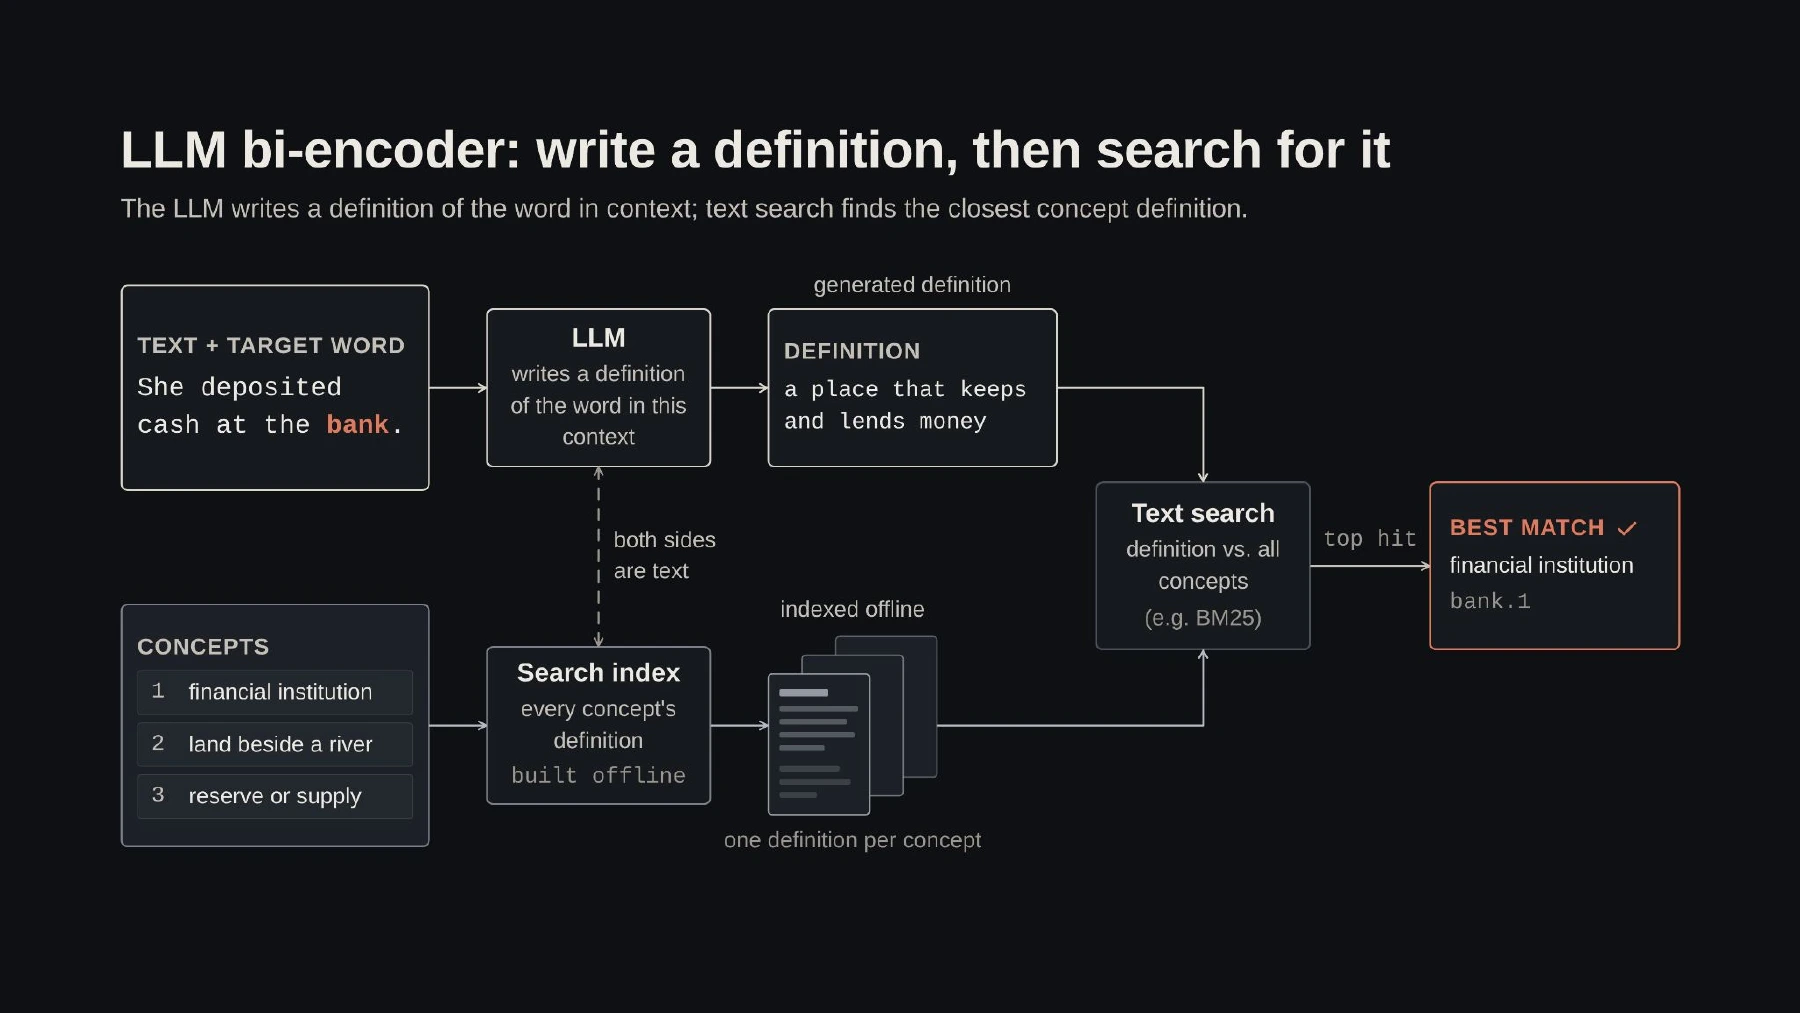
You can do something similar with an LLM. Instead of producing a vector directly, ask it to write a definition of the meaning used in the text. Then search your concept inventory for similar definitions.
For the hybrid version, give the retrieved candidates and the original text to another LLM: “Here are the possible concepts. Which one is used here?”
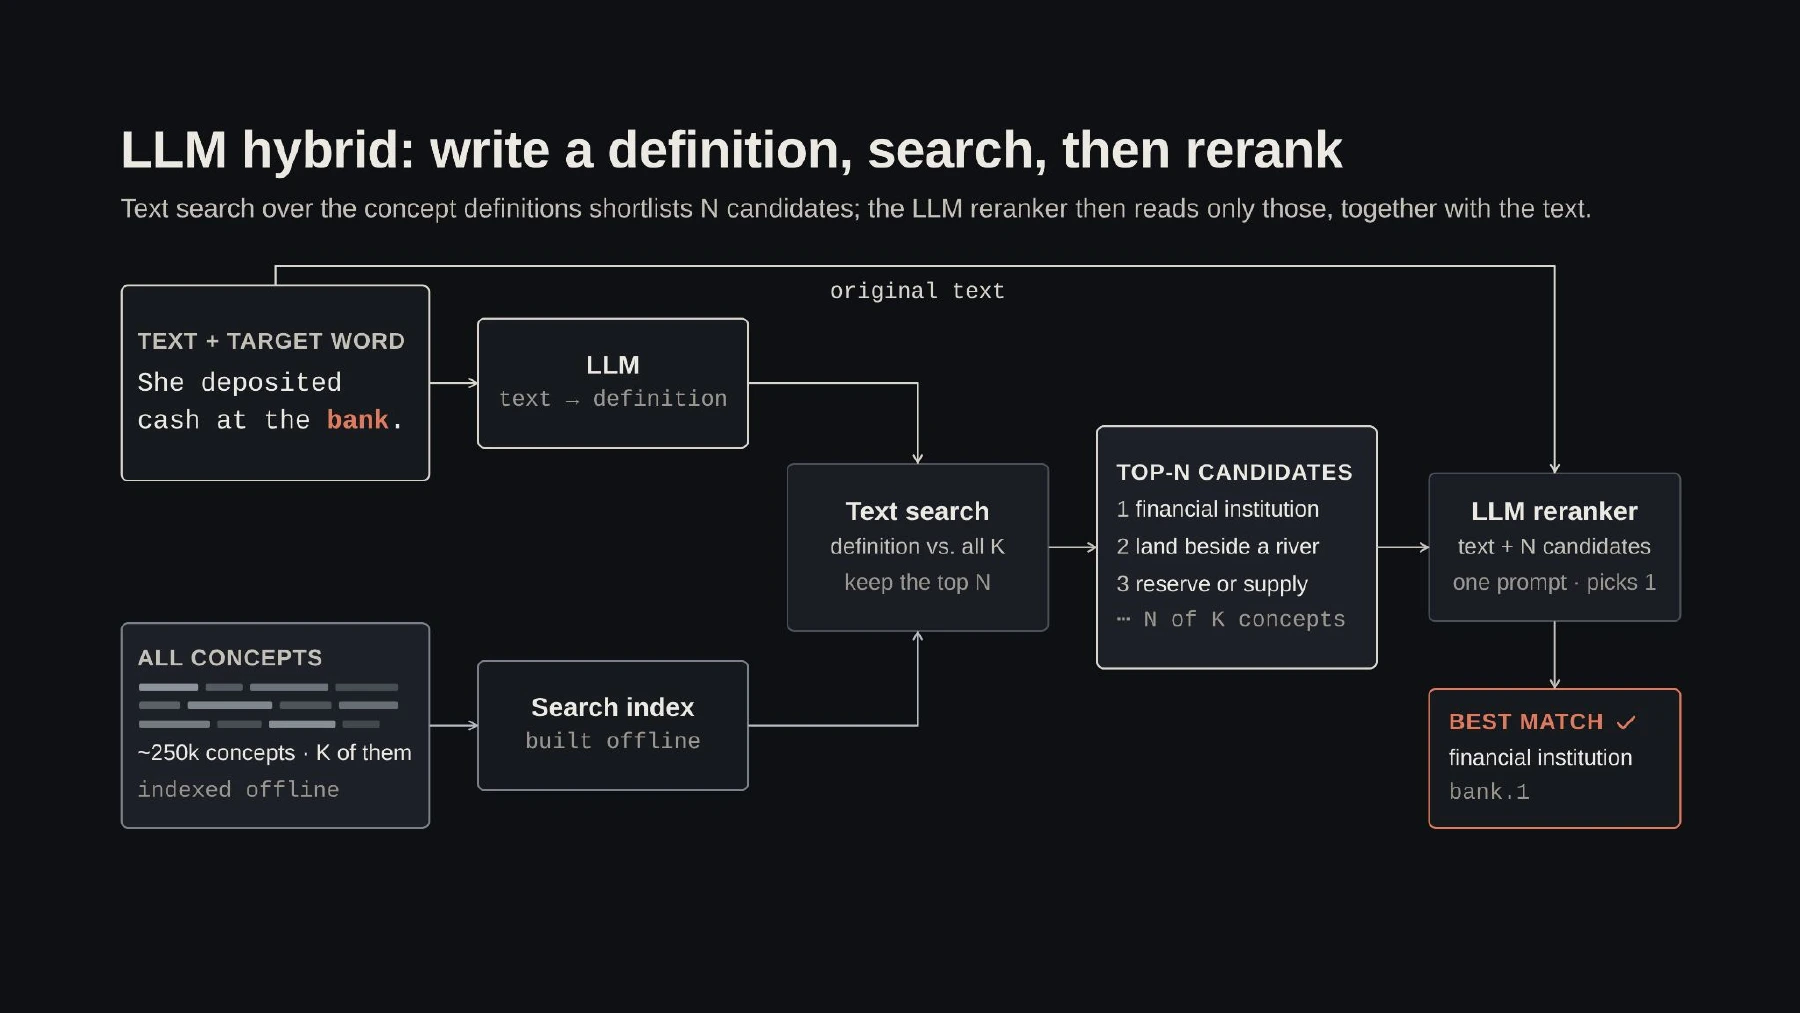
The inventory may contain tens of thousands of concepts. Giving every definition to the model on every request is impractical, so the preselection step matters.
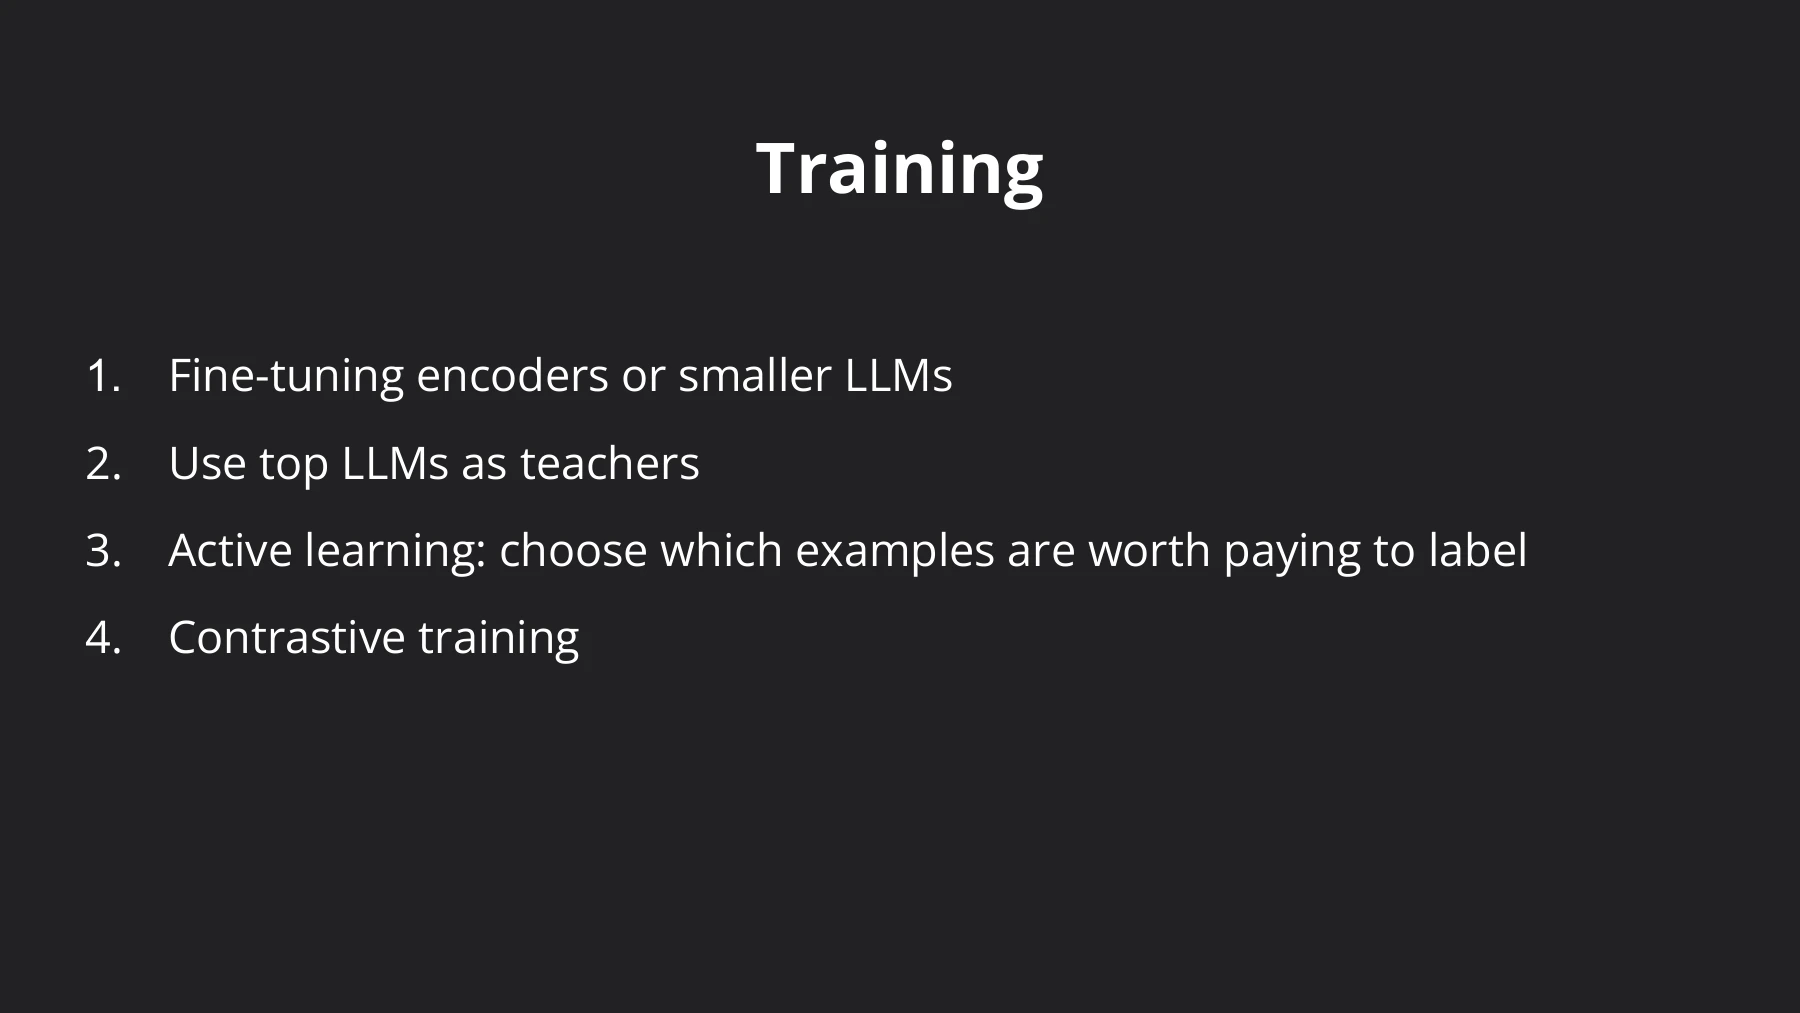
How do we train the smaller models? Fine-tune an encoder or a small LLM for this task, and use a strong, expensive LLM as a teacher to label a reasonably sized dataset. Our word-sense results show why that can work.
We can also choose the training examples more carefully. This is active learning: spend the labelling budget on the items that are most useful to the model.
Imagine you have labelled a million examples and trained an initial model. Look at the types of examples where it makes mistakes or has low confidence. Instead of labelling another random million, choose more examples of those types.
Then use contrastive training. Train the model to put a context close to its correct concept and further away from confusing alternatives. We want it to learn the distinctions that matter for this task.
That gives us a practical route to a model with a useful balance of price and quality. But there is a more fundamental question behind all of this.
Are concepts really separate things?
When you did the quiz, some definitions probably felt almost subjective. Is it this meaning or that one?
Mathematics has similar questions. Is multiplying seven by eight the same concept as multiplying eight by seven? What about multiplying four by ten and multiplying five by ten? Is it one rule — put a zero at the end — or separate pieces of knowledge?
We take the space of possible meanings and draw boundaries: this is one concept, this is another. Then our extractor takes a piece of text and says, “This is concept number one.” To estimate importance, we count how often each concept appears.
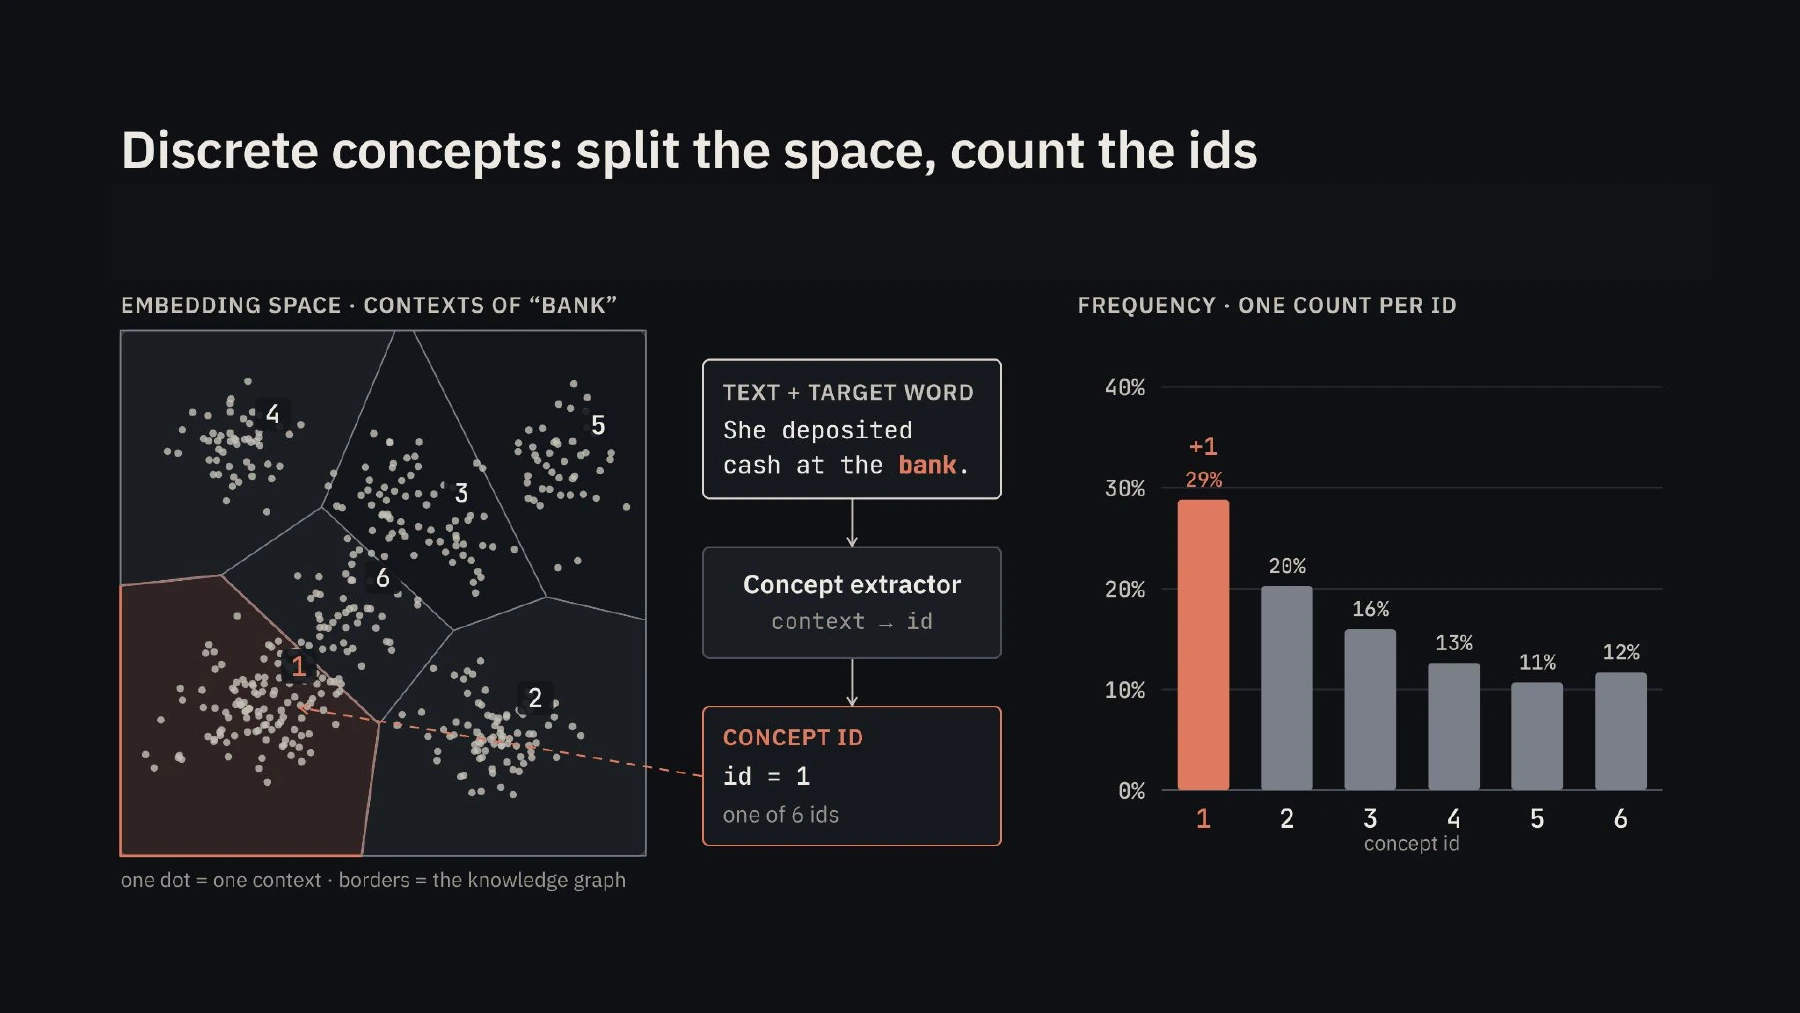
Could we work with the space directly? The knowledge graph would become a space of concept embeddings, and the extractor would say, “This meaning is here.”
Importance would become a density function: how frequently do meanings appear in this part of the space? For examples, we would search for something close enough for our purpose, rather than insist on exactly the same concept ID.
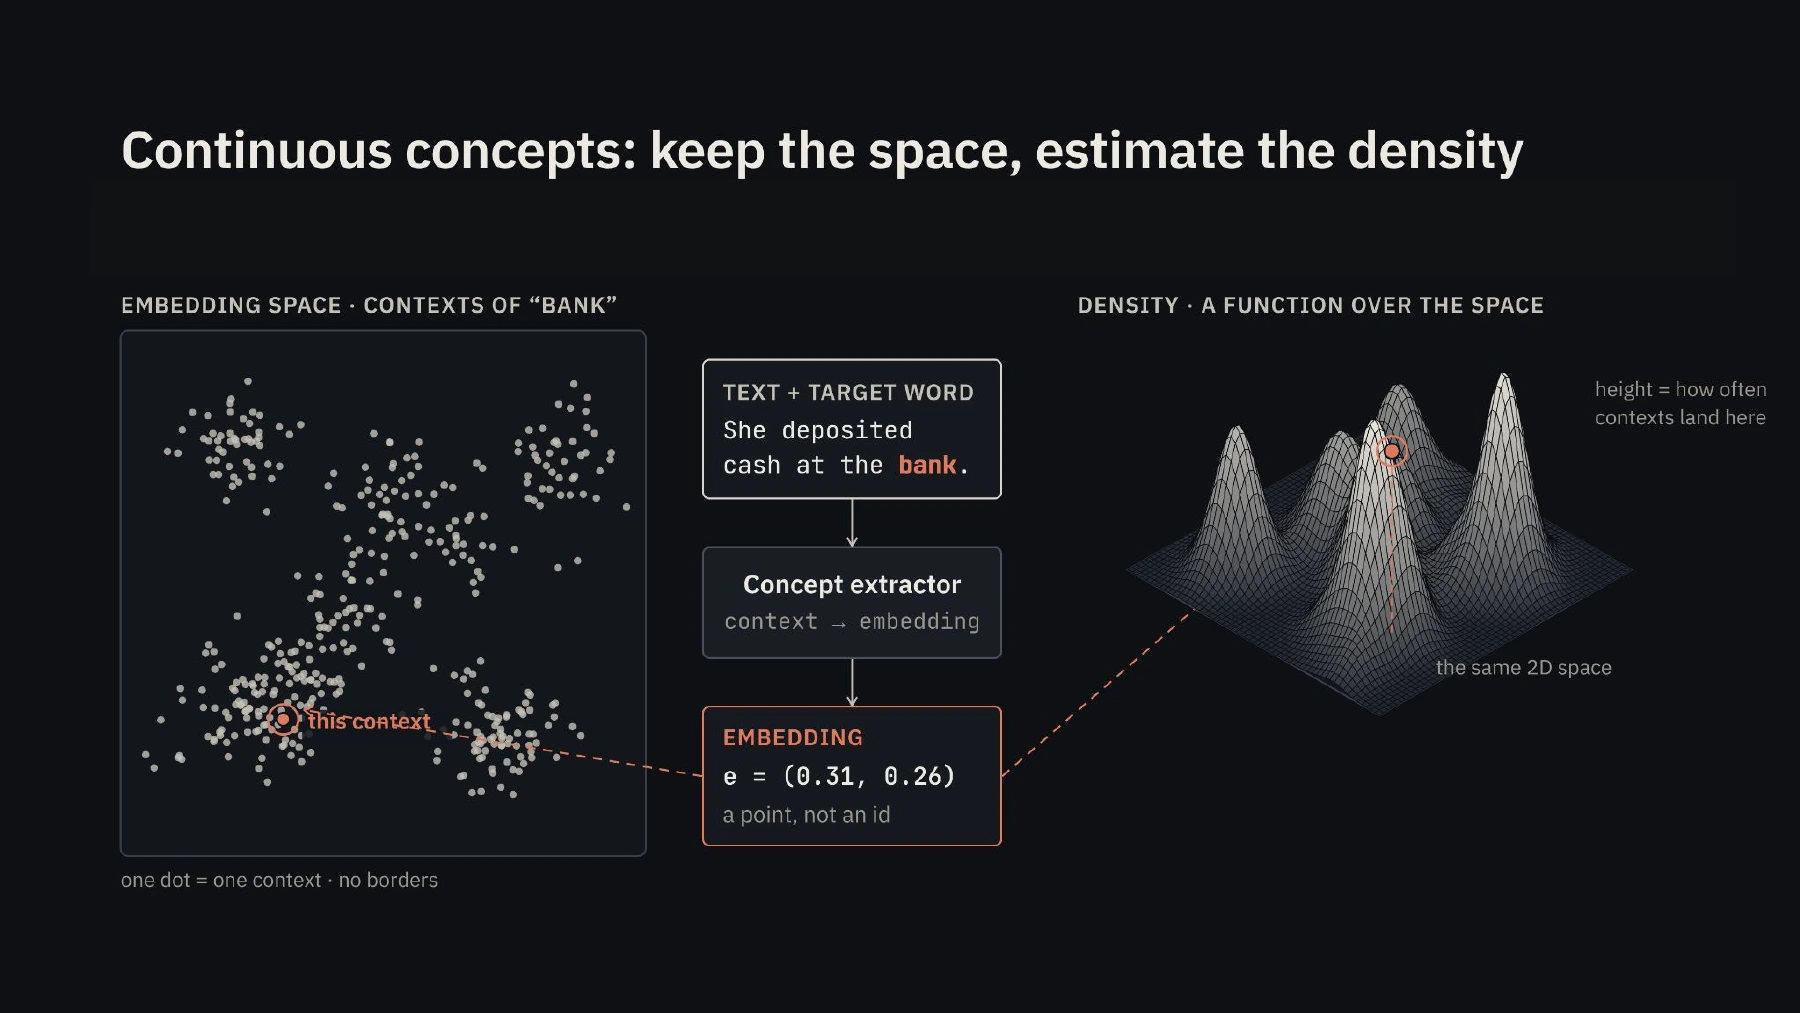
The hard part is getting the right distance. It needs to mean similarity for education. If you know this concept, how likely are you to know a nearby one?
Most embeddings were built for other purposes. They do not automatically give us that relationship. Building a space that does is one of the directions I would like to explore.