lexEN
Expert-reviewed labels for English word sense disambiguation.
lexEN v1 contains 4,861 English word-sense evaluation items with WordNet 3.0 candidate meanings, sentence context and three parallel answer keys: original Raganato, Maru2022 and lexEN. It starts from the 4,917-item Maru2022 ALL_NEW benchmark.
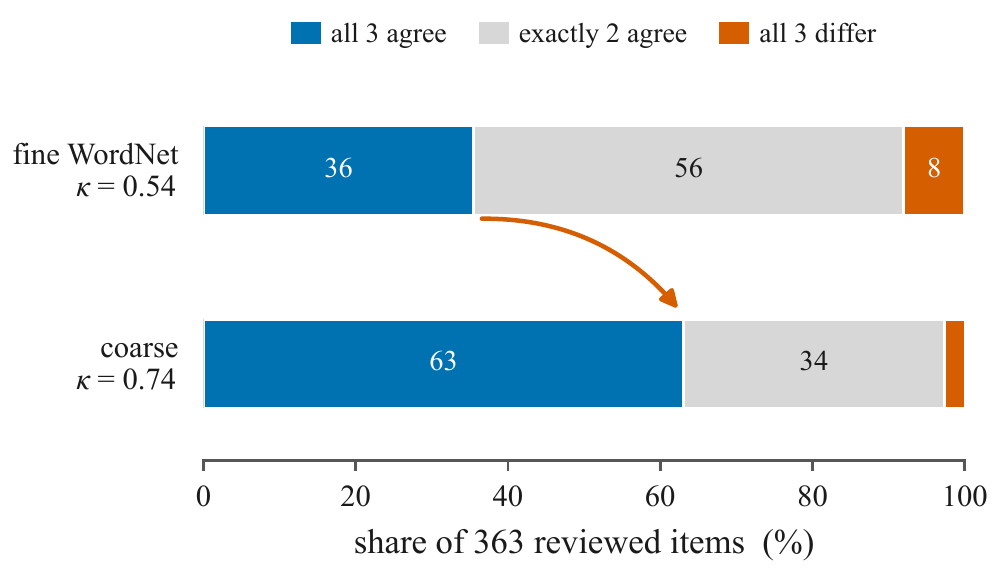
A panel of WSD models flagged 363 disputed items. Three professional lexicographers reviewed each independently, blind to the source label and one another’s decisions. A two-reviewer agreement rule changed 211 retained labels and removed 56 unanswerable or unresolved items. The other 4,554 items retain Maru2022 labels; the release includes the individual reviews, rationales and correction history.
Table 5 of our paper holds both predictions and the 4,861 retained items fixed. GPT-5.5 scores 85.4% against original Raganato labels, 91.8% against Maru2022 and 95.6% against lexEN. ConSeC moves from 81.8% to 84.2% to 84.9%. These are changes in evaluation labels, with no retraining or new model answers.
The release provides JSONL and Raganato-compatible XML and gold-key exports, plus mappings to broader Glite concepts. SenseBench can score the same predictions against each label layer and sense granularity.