Glite Get Started
Glite menu
Research

Concept extraction

We give the concept extractor text, audio or video, and it identifies the learning concepts.

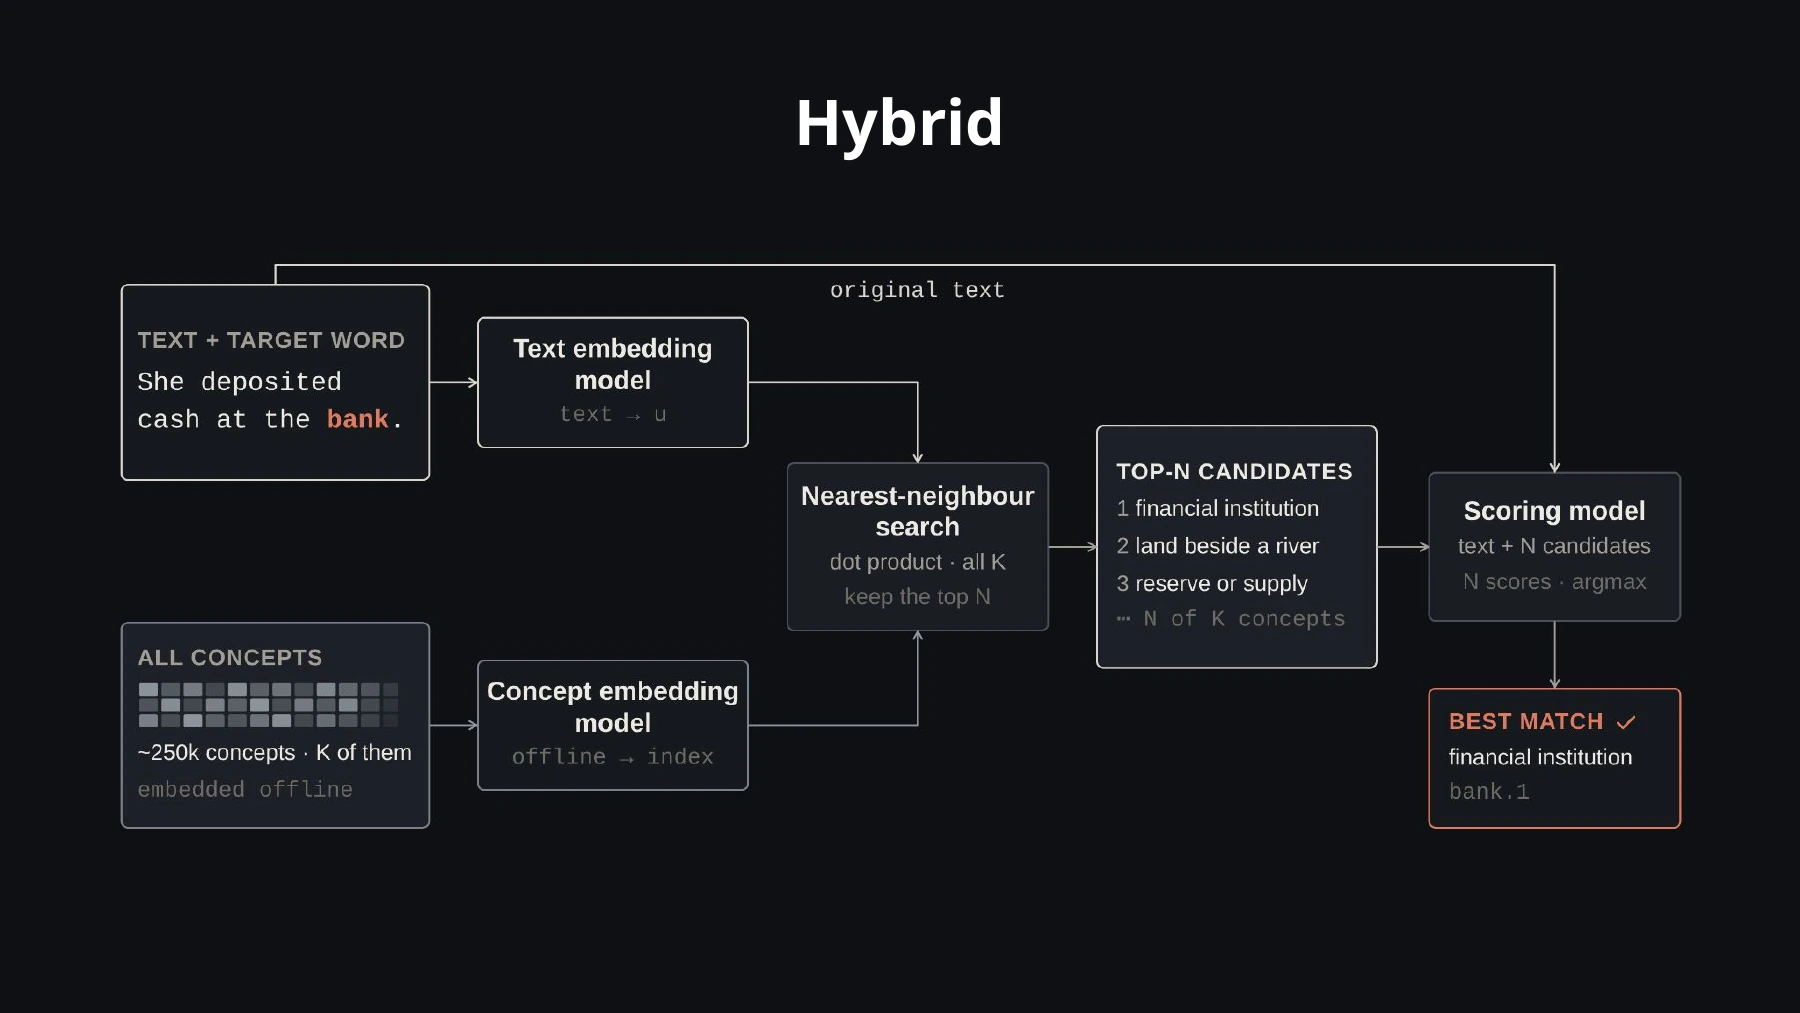
For English, a concept can be a particular word sense or expression. In mathematics, it might be a skill or a misconception revealed by an answer. Our current word sense research examines specialised models, LLMs, hybrid systems and the quality of the labels used to evaluate and train them.

Resources

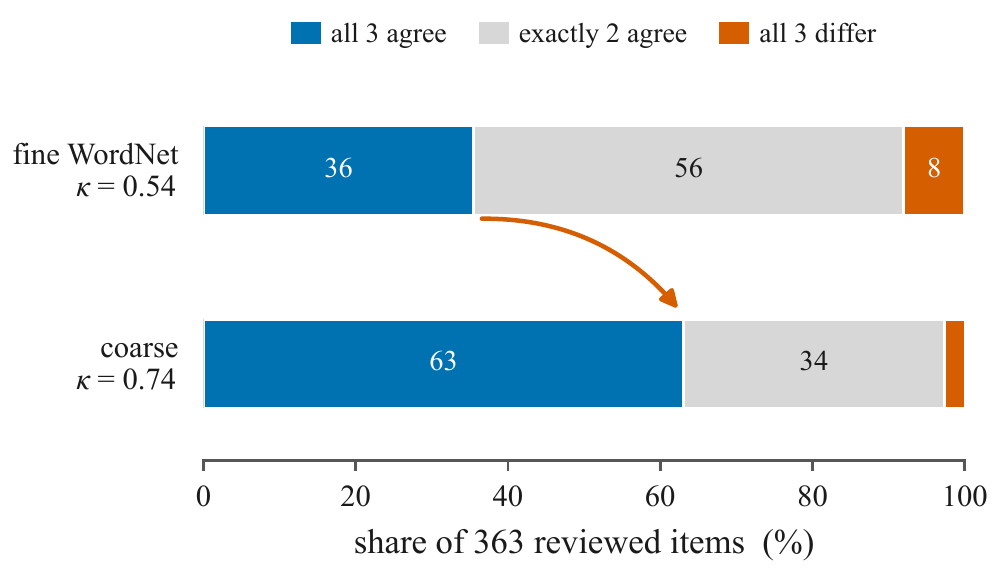
Lexicographer agreement on 363 reviewed items using fine WordNet senses and broader concepts.

lexEN

Expert-reviewed labels for English word sense disambiguation.

  • 4,861 test items, built from Maru2022.
  • Three lexicographers reviewed 363 disputed cases: 211 labels corrected, 56 items removed.
  • GPT-5.5 scores 91.8% with Maru labels → 95.6% with lexEN labels, using the same predictions.
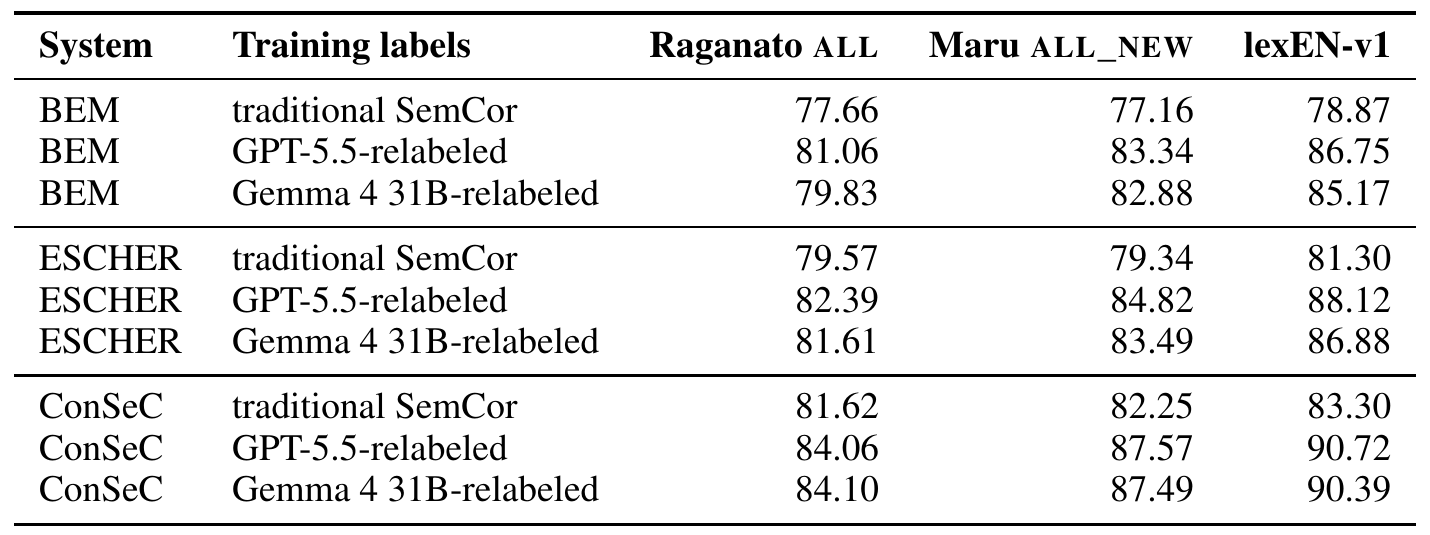
Controlled retraining results for BEM, ESCHER and ConSeC, comparing original and LLM-relabeled SemCor on Raganato ALL, Maru ALL_NEW and lexEN.

LLM-relabeled SemCor

LLM-generated replacement labels for the SemCor training corpus.

  • 226,036 training items, independently relabelled by GPT-5.5 and Gemma 4 31B.
  • GPT-5.5 labels lift ConSeC accuracy by 2.4 percentage points on Raganato ALL.
  • Same architecture and training recipe; BEM and ESCHER also improve.
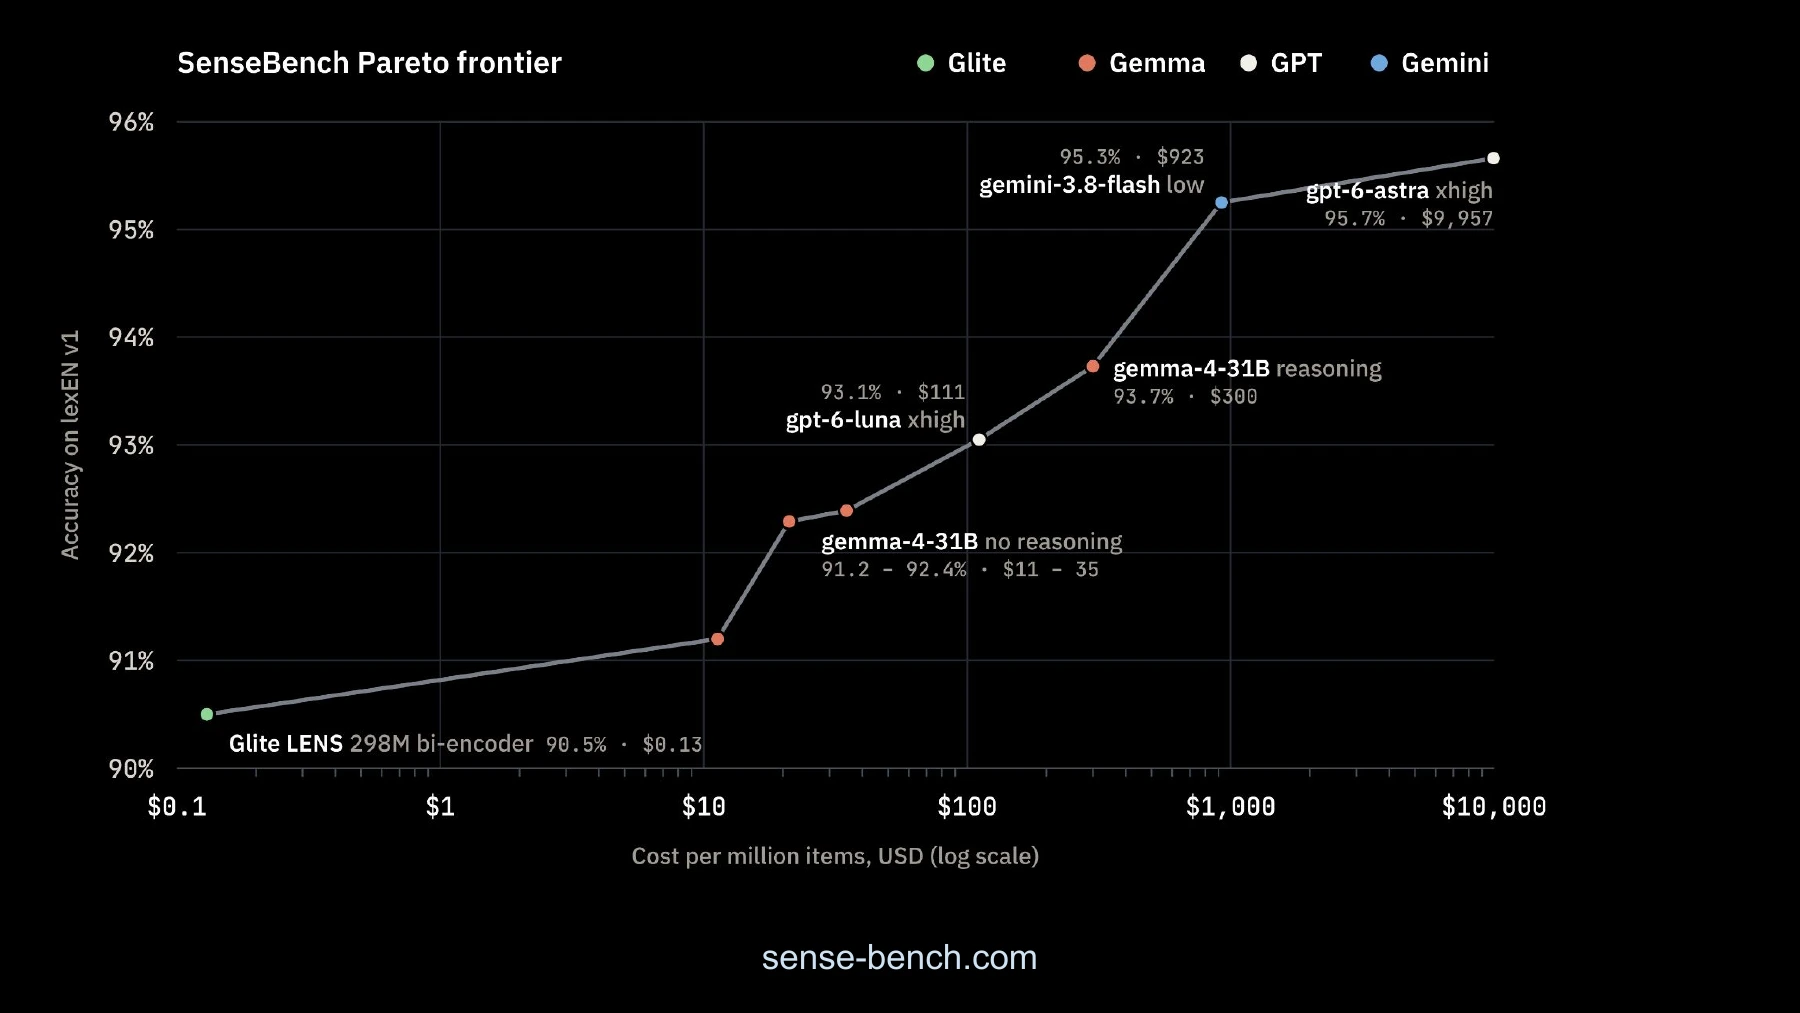
SenseBench chart comparing word-sense accuracy with cost per million items for Glite LENS and larger language models.

SenseBench

A benchmark of accuracy and cost in English word sense disambiguation.

  • 69 LLMs and 225 verified runs on 4,861 lexEN items.
  • Top fine-grained score: 95.66% (GPT 6 Astra, xhigh; 25 September 2026).
  • lexEN, Maru2022 and original Raganato answer keys; fine and broader senses.
  • Accuracy, cost, confidence intervals and raw responses for each run.
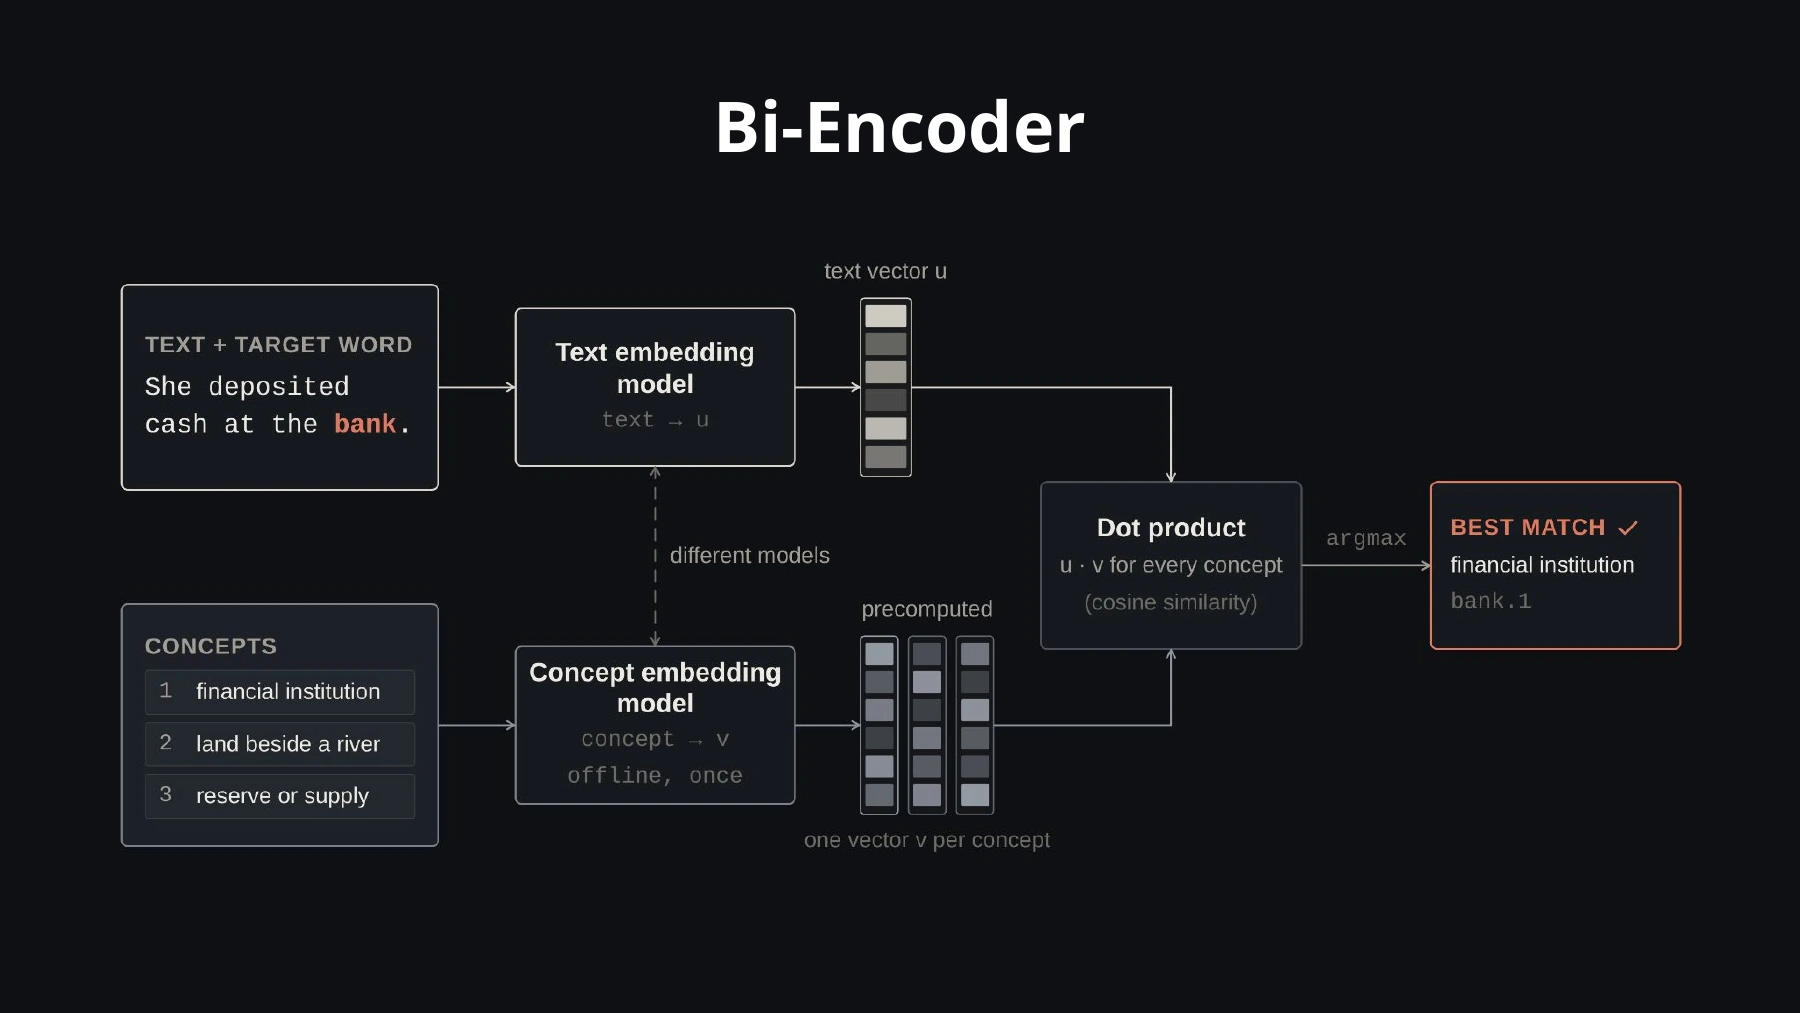
Bi-encoder architecture matching a word in context with candidate meanings through vector similarity.

Glite LENS

A bi-encoder for matching English words in context to their meanings.

  • 298M parameters; 89.69% fine-grained accuracy on lexEN.
  • ConSeC scores 84.88% and the top LLM 95.66% in the same evaluation.
  • About $0.13 per million decisions in measured self-hosted inference.

Related articles