SenseBench
A benchmark of accuracy and cost in English word sense disambiguation.
SenseBench evaluates English word sense disambiguation: a model receives a target word in context and its candidate WordNet senses, then selects a meaning. The 25 September 2026 snapshot contains 225 verified runs across 69 LLMs on all 4,861 lexEN v1 items.
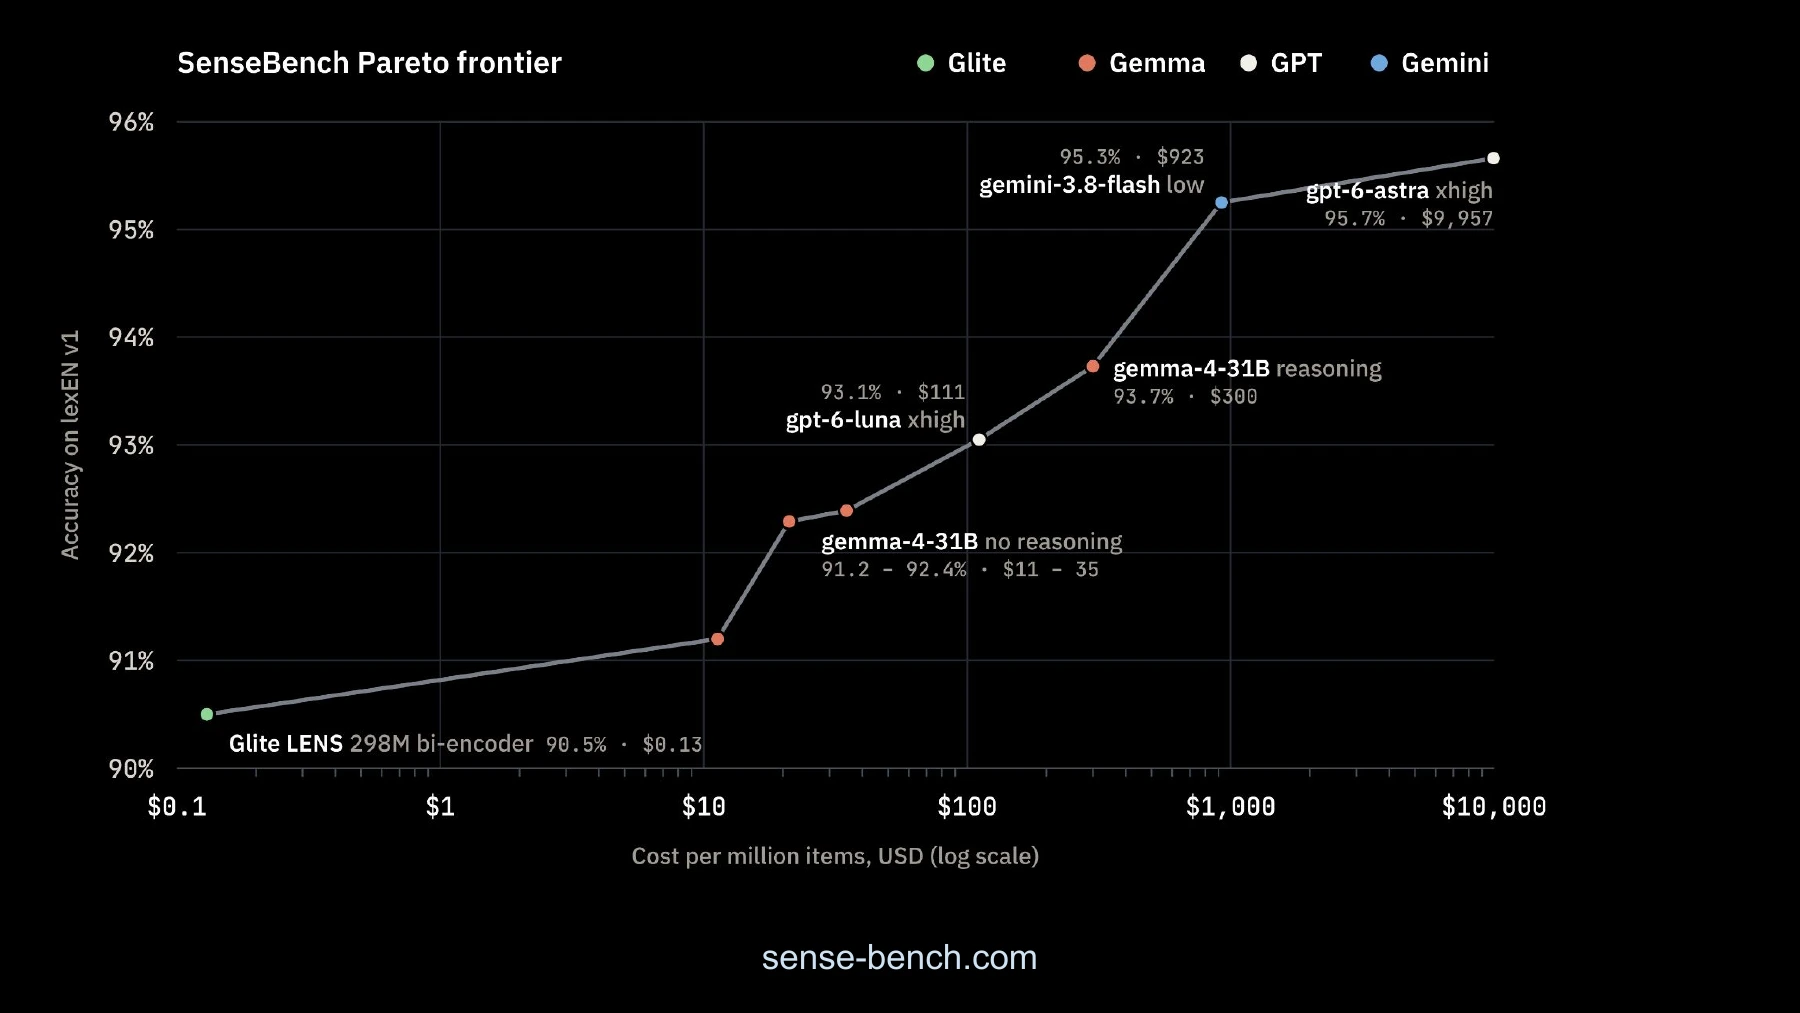
At WordNet fine granularity, GPT 6 Astra with xhigh reasoning leads at 95.66%: 4,650 correct answers, with a 95% confidence interval of 95.08–96.22%. GPT-5.5 scores 95.60%, Gemini 3.8 Flash 95.25% and Claude Fable 5 95.21%. On the same items and scoring rule, the published Glite LENS baseline scores 89.69% and ConSeC 84.88%.
Each run can be scored against three answer keys—lexEN v1, Maru2022 and original Raganato—and three sense inventories: fine WordNet senses, broader Glite concepts and the independent CSI grouping. These are nine scoring combinations for the same item set, not nine independent test datasets.
The leaderboard includes cost per million decisions, confidence intervals and paired significance tests. Every run retains its prompt, model configuration and raw responses; verification replays answer extraction and scoring before publication. Hosted models use recorded API pricing; self-hosted rows record hardware and inference settings and use published reference GPU rates.