LLM-relabeled SemCor
LLM-generated replacement labels for the SemCor training corpus.
The release supplies two aligned WordNet 3.0 label sets for the same 226,036 SemCor training instances: GPT-5.5 with low reasoning and Gemma 4 31B with reasoning. Each model sees the target in five preceding sentences and one following sentence, with candidate definitions, synonyms and examples.
GPT-5.5 changes 21.30% of the original labels; Gemma changes 21.85%. Each record preserves the original label, replacement label, raw answer and provenance. Four invalid GPT-5.5 outputs and 1,131 invalid Gemma outputs retain the original label in the released drop-in files. These percentages measure disagreement with SemCor, not a separately verified error rate.
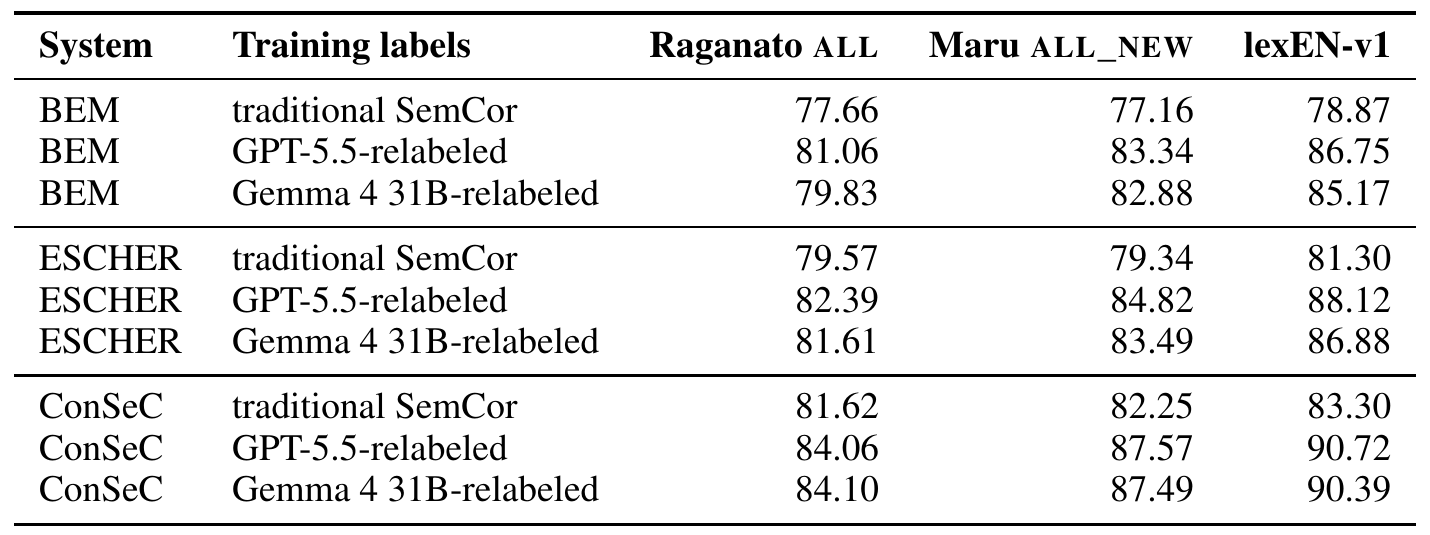
In the controlled retraining experiment, architecture, hyperparameters and training recipe stay fixed. With GPT-5.5 labels, Raganato ALL accuracy rises from 77.66% to 81.06% for BEM, 79.57% to 82.39% for ESCHER and 81.62% to 84.06% for ConSeC. On Maru ALL_NEW, ConSeC rises from 82.25% to 87.57%. Gemma labels also improve all three systems; ConSeC reaches 84.10% on Raganato ALL.
The repository includes compressed gold-key files, per-instance JSONL, checksums and a script that reconstructs a training corpus from your existing SemCor XML. The paper’s Table 12 and the reproduction repository contain the complete before-and-after results.